Как получить план выполнения SQL в Oracle
Узнайте, как получить расчетный и фактический план выполнения SQL при использовании команд Oracle EXPLAIN PLAN ДЛЯ или GATHER_PLAN_STATISTICS.
- Автор записи
Вступление
В этой статье мы рассмотрим, как мы можем получить план выполнения SQL в Oracle.
При настройке производительности план выполнения незаменим, так как он позволяет понять операции, выполняемые базой данных при выполнении определенного SQL-запроса.
Каков план выполнения SQL
Как я объяснил в этой статье , SQL описал Что а не то Как , и это одна из основных причин, по которой SQL был самым популярным способом запроса базы данных на протяжении более 40 лет.
При выполнении SQL-запроса база данных сначала проанализирует его и сгенерирует AST (Абстрактное синтаксическое дерево) для входящего запроса. Анализатор также проверяет синтаксис SQL-запроса и проверяет, существуют ли ресурсы базы данных, на которые ссылаются. Анализатор может переписать входящий запрос, чтобы оптимизировать его выполнение, не влияя на логику выборки результирующего набора.
Сгенерированное дерево запросов отправляется оптимизатору, которому необходимо определить наилучший способ извлечения данных, необходимых для текущего SQL-запроса. Таким образом, оптимизатор создает план выполнения, представляющий собой список операций, которые необходимо выполнить для удовлетворения требований SQL – запроса.
Полученный план выполнения отправляется Исполнителю, который запускает его и отправляет полученные данные обратно клиенту базы данных.
Этапы обработки и выполнения SQL можно визуализировать на следующей диаграмме.
Предполагаемый план выполнения SQL
Предполагаемый план выполнения генерируется оптимизатором без выполнения SQL-запроса. Вы можете сгенерировать предполагаемый план выполнения из любого клиента SQL, используя ОБЪЯСНИТЬ ПЛАН ДЛЯ или вы можете использовать Oracle SQL Developer для этой задачи.
ОБЪЯСНИТЕ ПЛАН ДЛЯ
При использовании Oracle, если вы добавляете команду ОБЪЯСНИТЬ ПЛАН ДЛЯ к заданному SQL-запросу, база данных сохранит предполагаемый план выполнения в соответствующей таблице PLAN_TABLE :
Чтобы просмотреть предполагаемый план выполнения, вам необходимо использовать DBMS_XPLAN.DISPLAY , как показано в следующем примере:
Параметр ВСЕ +СХЕМА форматирование позволяет получить более подробную информацию о предполагаемом плане выполнения, чем при использовании параметра форматирования по умолчанию.
Предполагаемый план будет выглядеть примерно так:
Обратите внимание, что некоторые столбцы были удалены, чтобы
Разработчик Oracle SQL
Если у вас установлен SQL Developer, вы можете легко получить расчетный план выполнения для любого SQL-запроса без необходимости добавлять ПЛАН ОБЪЯСНЕНИЯ ДЛЯ команды :
Фактический план выполнения SQL
Фактический план выполнения SQL генерируется оптимизатором при выполнении SQL-запроса. Таким образом, в отличие от предполагаемого плана выполнения, вам необходимо выполнить SQL-запрос, чтобы получить его фактический план выполнения.
Фактический план не должен существенно отличаться от расчетного, если табличная статистика была должным образом собрана базовой реляционной базой данных.
Подсказка запроса GATHER_PLAN_STATISTICS
Чтобы указать Oracle хранить фактический план выполнения для данного SQL-запроса, вы можете использовать подсказку GATHER_PLAN_STATISTICS запрос:
Для визуализации фактического плана выполнения вы можете использовать DBMS_XPLAN.DISPLAY_CURSOR To visualize the actual execution plan, you can use DBMS_XPLAN.DISPLAY_CURSOR
И фактический план будет выглядеть так:
Вы также можете использовать подсказку GATHER_PLAN_STATISTICS запроса для проверки плана выполнения SQL, связанного с данным запросом JPQL или API критериев.
Для получения более подробной информации об этой теме ознакомьтесь с этой статьей .
Включите СТАТИСТИКУ на уровне подключения к БД
Если вы хотите получить планы выполнения для всех запросов, созданных в рамках данного сеанса, вы можете установить параметр STATISTICS_LEVEL сеанса в ВСЕ :
Это будет иметь тот же эффект, что и установка подсказки GATHER_PLAN_STATISTICS запроса для каждого запроса на выполнение. Таким образом, как и в случае с подсказкой GATHER_PLAN_STATISTICS запроса, вы можете использовать DBMS_XPLAN.DISPLAY_CURSOR для просмотра фактического плана выполнения.
Вам следует сбросить параметр STATISTICS_LEVEL в режим по умолчанию, как только вы закончите сбор интересующих вас планов выполнения. Это очень важно, особенно если вы используете пул соединений, а в соединениях с базой данных отказано.
Вывод
Знание разницы между расчетным и фактическим планом выполнения SQL очень важно при использовании системы реляционных баз данных.
Если вы хотите ускорить определенный SQL-запрос, вам необходимо проверить план выполнения, чтобы определить, что именно вызывает медленное выполнение запроса. Без плана выполнения SQL невозможно определить, что база данных может делать под капотом при выполнении данного SQL-запроса.
Soft — Consulting
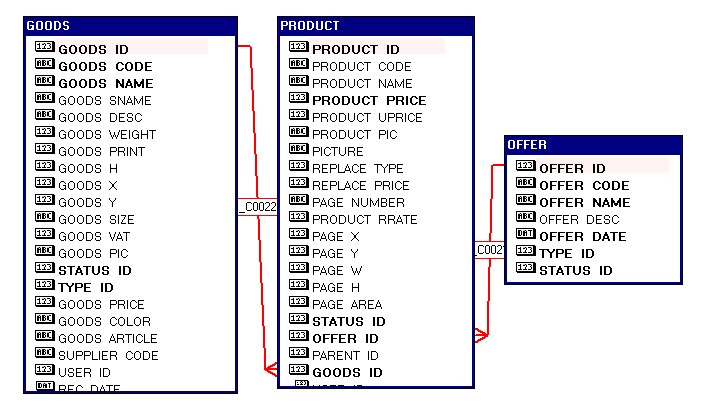
Данные рекомендации взяты мной из руководства Oracle по настройке базы данных, со временем они практически не меняются, посмотреть их можно здесь, это глава 11.5. Ссылка может не работать, все зависит от того, как долго Oracle решит хранить этот фрагмент документации в интернете.
Не используйте SQL-функции в предикатах. Любое выражение в котором используется колонка (expression), например функция, использующая колонку, как аргумент, приведет к тому, что индекс для данной колонки (если он есть) использоваться не будет, даже если это уникальный индекс. Хотя, если для колонки имеется составной индекс (function-based) на основе применяемой в предикате функции, то он может быть использован.
где numexpr выражение числового типа, то Oracle преобразует ваше условие в:
и индекс использован не будет.
Где по числовой колонке numcol построен индекс.
План запроса.
Практически любую задачу по получению каких-либо результатов из базы данных можно решить несколькими способами, т.е. написать несколько разных запросов, которые дадут один и тот же результат. Это, однако не означает, что база данных эти запросы будет выполнять по-разному. Также неверно мнение о том, что структура запроса может повлиять на то, как Oracle будет его выполнять, это касается порядка временных таблиц, JOINS и условий отбора в WHERE. Решение о том, как построить запрос принимает оптимизатор Oracle. Алгоритм получения сервером данных для конкретного запроса называют планом запроса.
Практически все продукты для работы с базой данных Oracle позволяют просмотреть план конкретного запроса. Так как слушатели этих лекций используют PL/SQL Developer, то для получения плана запроса в нем необходимо сделать следующее:
Существует стандартный механизм получения плана запроса. Для этого используется конструкция (команда) EXPLAIN PLAN FOR:
План запроса будет выведен в виде таблицы с одним полем, выглядит он так:
Важно ! Во всех планах запросов, первостепенное значение имеют колонки операций и названия объектов над которыми эти операции производятся. Все остальные колонки имеют оценочный характер, часть из них формируется на основе статистики, которая может устареть или вообще отсутствовать. При анализе плана запроса вы должны представлять объемы записей в таблицах, а также примерный алгоритм соединения таблиц.
В приведенном выше примере показан план запроса, полученный с помощью EXPLAIN PLAN FOR, более наглядную картину дает окно плана запроса в PL/SQL Developer:
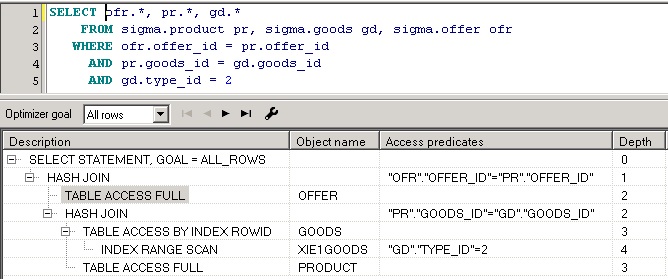
План всегда имеет иерархическую структуру. Операция соединения результирующих наборов оперирует парами дочерних операций. Операция получения данных может использовать вспомогательную операцию, такую, например, как сканирование индекса.
Данные результирующих наборов получаются в порядке следования этих наборов в плане запроса. Операция получения данных результирующего набора может состоять из нескольких шагов, которые характеризуются глубиной операции (колонка Depth).
При анализе плана в первую очередь необходимо обращать внимание на способы, с помощью которых получены данные результирующих наборов.
Некоторые термины в плане запроса.
План запроса имеет форму таблицы, один из столбцов которой описывает тип производимых сервером операций. Вот некоторые из них, которые встречаются наиболее часто:
Анализ плана запроса.
При анализе плана запроса вам необходимо примерно представлять объемы записей в таблицах и наличие у них индексов, которые могут пригодиться при фильтрации записей. Для доступа к данным Oracle использует несколько стратегий, какие из них выбраны для каждой из таблиц можно понять из плана запроса. При просмотре плана, вам необходимо решить, правильная ли выбрана стратегия в том или ином случае. Ниже приведены краткие описания способов доступа и механизмов отбора записей при соединениях результирующих наборов.
Full Table Scan (Table Access Full).
Может показаться, что доступ к данным таблицы быстрее осуществлять через индекс, но это не так. Иногда дешевле прочитать всю таблицу целиком, чем прочитать, например, 80% записей таблицы через индекс, так как чтение индекса тоже требует ресурсов. Очень не желательна ситуация, когда эта операция стоит первой в объединении наборов записей и таблица, которая читается полностью, большая. Еще хуже ситуация с большой таблицей на второй позиции в объединении, это означает, что она также будет прочитана полностью, как минимум, один раз, а если объединение производится через NESTED LOOPS, то таблица будет читаться несколько раз, поэтому запрос будет работать очень долго.
Nested Loops.
Такое соединение может использоваться оптимизатором, когда небольшой основной набор записей (стоит первым в плане запроса) объединяется с помощью условия, позволяющего эффективно выбрать записи из второго набора. Важным условием успешного использования такого соединения является наличие связи между основным и второстепенным набором записей. Если такой связи нет, то для каждой записи в первом наборе, из второго набора будут извлекаться одни и те же записи, что может привести к значительному увеличению времени запроса. Если вы видите, что в плане запроса применен NESTED LOOPS, а соединяемые наборы не удовлетворяют этому условию, то налицо ошибка.
Hash Joins.
Используется при соединении больших наборов данных. Оптимизатор использует наименьший из наборов данных для построения в памяти хэш-таблицы по ключу соединения. Затем он сканирует большую таблицу, используя хэш-таблицу для нахождения записей, которые удовлетворяют условию объединения.
Оптимизатор использует HASH JOIN, если наборы данных соединяются с помощью операторов и ключевых слов эквивалентности (=, AND) и если присутствует одно из условий:
■ Необходимо соединить наборы данных большого объема.
■ Большая часть небольшого набора данных должна быть использована в соединении.
Sort Merge Join.
Данное соединение может быть применено для независимых наборов данных. Обычно Oracle выбирает такую стратегию, если наборы данных уже отсортированы ранее, и если дальнейшая сортировка результата соединения не требуется. Обычно это имеет место для наборов, которые соединяются с помощью операторов , >=. Для этого типа соединения нет понятия главного и вспомогательного набора данных, сначала оба набора сортируются по общему ключу, а затем сливаются в одно целое. Если какой-то из наборов уже отсортирован, то повторная сортировка для него не производится.
Cartesian Joins.
Это соединение используется, когда одна и более таблиц не имеют никаких условий соединения с какой-либо другой таблицей в запросе. В этом случае произойдет объединение каждой записи из одного набора данных с каждой записью в другом. Такое соединение может быть выбрано между двумя небольшими таблицами, а в дальнейшем этот набор данных будет соединен с другой большой таблицей. Наличие такого соединения может обозначать присутствие серьезных проблем в запросе, особенно, если соединяемые таблицы по MERGE JOIN CARTESIAN. В этом случае, возможно, упущены дополнительные условия соединения наборов данных.
Хинты.
Хинт — это ключевое слово, иногда с набором параметров, которое может повлиять на оптимизатор при составлении плана запроса. Другими словами, с помощью хинтов вы можете попытаться изменить способ с помощью которого будут получены или обработаны данные (хинты есть не только у операторов SELECT).
Если у вас есть желание более детально ознакомиться с хинтами, то я рекомендовал бы вам просмотреть эту статью.
Использование хинтов.
Хинт ставится после ключевого слова, которое определяет некую цельную конструкцию запроса, в данном разделе речь пойдет о хинтах в запросах к данным, т.е. тех, которые оформляются оператором SELECT и ключевых словах, используемых в сочетании с ним. Хинт указывается в закрытом комментарии после оператора:
В данном примере используется хинт RULE.
Этот хинт официально не поддерживается с версии Oracle 10G. При его успешном применении включается оптимизация по определенным правилам (RBO — Rule Based Optimization). Данный хинт может быть полезен, если у вас сложный запрос с неэффективным планом выполнения и использование других хинтов может занять время, которого мало. Если в запросе не пропущены какие-то JOINS или условия и вы считаете, что он написан верно, то есть достаточно большая вероятность, что RBO построит верный план.
В 11G этот хинт пока работает с некоторыми ограничениями, важны для практической работы следующие:
■ В запросе не должны использоваться другие хинты.
■ Не должен использоваться синтаксис ANSI (left join | full outer join …)
FIRST_ROWS.
Данный хинт дает указание оптимизатору выбрать такой план запроса при котором первые записи результатов будут получены максиально быстрым способом. Хорош при отладке запроса, чтобы убедиться, что выдается то, что необходимо. Если предполагается, что запрос вернет много записей, то при использовании такого хинта он может работать дольше.
ORDERED / LEADING.
При использовании этого хинта оптимизатор соединяет наборы данных в том порядке, в каком они следуют после оператора FROM. Вот пример разных последовательностей:
Порядок наборов данных необходимо выбирать аккуратно, чтобы соединяемые объекты имели какое-то условие связи в WHERE или после ключевого слова ON. Например в приведенном выше примере 4 версия списка во FROM приведет к перемножению таблиц GOODS и OFFER, так как они не связаны друг с другом условиями.
Данный хинт часто бывает полезен, если статистика по таблицам не собрана, план запроса не верный, и вам точно известно, как должны соединяться таблицы. При использовании данного хинта старайтесь выстроить порядок соединения так, чтобы тяжесть обработки данных следовала в сторону увеличения, т.е. сначала соедините наборы поменьше или с хорошими условиями отбора, чтобы результат их соединения был наименьшим по количеству записей, затем подключайте наборы данных большего размера.
Более удобен в использовании хинт LEADING. Он позволяет соединить наборы данных в порядке перечисления их (или их алиасов) в списке аргументов хинта:
Порядок связи в этом примере будет такой: product -> offer -> goods. Использование этого хинта предпочтительнее при отладке, если список наборов данных большой.
MATERIALIZE.
Дает указание оптимизатору построить временную таблицу (материализовать результаты) для запроса, к которому этот хинт применяется, работает только в конструкции WITH. Очень полезен при обработке больших объемов данных, так как позволяет разбить запрос на части, в этом случае улучшается читабельность запроса, а также может быть получен правильный план. Пример использования:
План запроса выглядит так:
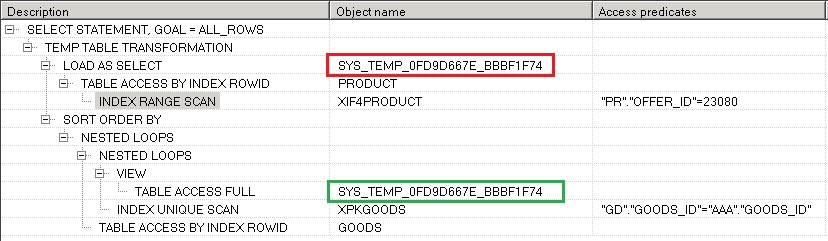
Красным цветом помечена таблица при ее создании, зеленым ее использование в соединении.
INDEX.
Дает указание оптимизатору использовать индекс при чтении данных из таблицы. Полезен тем, что может предотвратить чтение всего содержимого таблицы, если вы считаете, что этого делать не нужно. Пример использования:
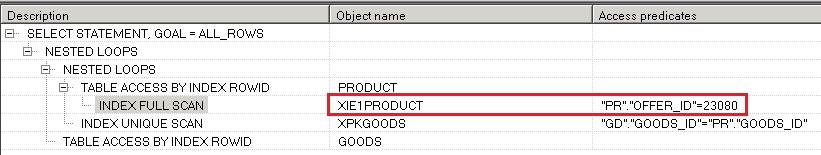
Этот хинт сработает в том случае, если у таблицы есть указываемый индекс, и его можно использовать на основе одного или нескольких условий при получении данных таблицы. В приведенном примере в составе индекса есть поле OFFER_ID на второй позиции и он может быть использован, план запроса выглядит в этом случае так:
Комбинации хинтов.
Использование комбинации хинтов допустимо. Нужный эффект можно получить, если хинты в одном запросе не протеворечат друг другу. При записи хинты разделяются пробелами:
В данном примере используется хинт для установки порядка соединения наборов данных и способа доступа к таблице, противоречия в их использовании нет.
Pl sql developer план запроса как посмотреть
Knowledge of how to explain a statement and display its plan is essential to SQL tuning.
6.1 Introduction to Execution Plans
An execution plan is the sequence of operations that the database performs to run a SQL statement.
6.1.1 Contents of an Execution Plan
The execution plan operation alone cannot differentiate between well-tuned statements and those that perform suboptimally.
The plan consists of a series of steps. Every step either retrieves rows of data physically from the database or prepares them for the user issuing the statement. The following plan shows a join of the employees and departments tables:
The row source tree is the core of the execution plan. The tree shows the following information:
The join order of the tables referenced by the statement
In the preceding plan, employees is the outer row source and departments is the inner row source.
An access path for each table mentioned in the statement
In the preceding plan, the optimizer chooses to access employees using an index scan and departments using a full scan.
A join method for tables affected by join operations in the statement
In the preceding plan, the optimizer chooses a nested loops join.
Data operations like filter, sort, or aggregation
In the preceding plan, the optimizer filters on last names that begin with T and matches on department_id .
In addition to the row source tree, the plan table contains information about the following:
Optimization, such as the cost and cardinality of each operation
Partitioning, such as the set of accessed partitions
Parallel execution, such as the distribution method of join inputs
6.1.2 Why Execution Plans Change
Execution plans can and do change as the underlying optimizer inputs change.
To avoid possible SQL performance regression that may result from execution plan changes, consider using SQL plan management.
6.1.2.1 Different Schemas
Schemas can differ for various reasons.
Principal reasons include the following:
The execution and explain plan occur on different databases.
The user explaining the statement is different from the user running the statement. Two users might be pointing to different objects in the same database, resulting in different execution plans.
Schema changes (often changes in indexes) between the two operations.
6.1.2.2 Different Costs
Even if the schemas are the same, the optimizer can choose different execution plans when the costs are different.
Some factors that affect the costs include the following:
Data volume and statistics
Bind variable types and values
Initialization parameters set globally or at session level
6.2 Generating Plan Output Using the EXPLAIN PLAN Statement
The EXPLAIN PLAN statement enables you to examine the execution plan that the optimizer chose for a SQL statement.
6.2.1 About the EXPLAIN PLAN Statement
The EXPLAIN PLAN statement displays execution plans that the optimizer chooses for SELECT , UPDATE , INSERT , and DELETE statements.
EXPLAIN PLAN output shows how the database would have run the SQL statement when the statement was explained. Because of differences in the execution environment and explain plan environment, the explained plan can differ from the actual plan used during statement execution.
When the EXPLAIN PLAN statement is issued, the optimizer chooses an execution plan and then inserts a row describing each step of the execution plan into a specified plan table. You can also issue the EXPLAIN PLAN statement as part of the SQL trace facility.
The EXPLAIN PLAN statement is a DML statement rather than a DDL statement. Therefore, Oracle Database does not implicitly commit the changes made by an EXPLAIN PLAN statement.
Oracle Database SQL Language Reference to learn about the EXPLAIN PLAN statement
6.2.1.1 About PLAN_TABLE
PLAN_TABLE is the default sample output table into which the EXPLAIN PLAN statement inserts rows describing execution plans.
Oracle Database automatically creates a global temporary table PLAN_TABLE$ in the SYS schema, and creates PLAN_TABLE as a synonym. All necessary privileges to PLAN_TABLE are granted to PUBLIC . Consequently, every session gets its own private copy of PLAN_TABLE in its temporary tablespace.
You can use the SQL script catplan.sql to manually create the global temporary table and the PLAN_TABLE synonym. The name and location of this script depends on your operating system. On UNIX and Linux, the script is located in the $ORACLE_HOME/rdbms/admin directory. For example, start a SQL*Plus session, connect with SYSDBA privileges, and run the script as follows:
The definition of a sample output table PLAN_TABLE is available in a SQL script on your distribution media. Your output table must have the same column names and data types as this table. The common name of this script is utlxplan.sql . The exact name and location depend on your operating system.
Oracle Database SQL Language Reference for a complete description of EXPLAIN PLAN syntax.
6.2.1.2 EXPLAIN PLAN Restrictions
Oracle Database does not support EXPLAIN PLAN for statements performing implicit type conversion of date bind variables.
With bind variables in general, the EXPLAIN PLAN output might not represent the real execution plan.
From the text of a SQL statement, TKPROF cannot determine the types of the bind variables. It assumes that the type is VARCHAR , and gives an error message otherwise. You can avoid this limitation by putting appropriate type conversions in the SQL statement.
6.2.2 Explaining a SQL Statement: Basic Steps
Use EXPLAIN PLAN to store the plan for a SQL statement in PLAN_TABLE .
This task assumes that a sample output table named PLAN_TABLE exists in your schema. If this table does not exist, then run the SQL script catplan.sql .
To execute EXPLAIN PLAN , you must have the following privileges:
You must have the privileges necessary to insert rows into an existing output table that you specify to hold the execution plan
You must also have the privileges necessary to execute the SQL statement for which you are determining the execution plan. If the SQL statement accesses a view, then you must have privileges to access any tables and views on which the view is based. If the view is based on another view that is based on a table, then you must have privileges to access both the other view and its underlying table.
To examine the execution plan produced by an EXPLAIN PLAN statement, you must have the privileges necessary to query the output table.
To explain a statement:
Start SQL*Plus or SQL Developer, and log in to the database as a user with the requisite permissions.
Include the EXPLAIN PLAN FOR clause immediately before the SQL statement.
The following example explains the plan for a query of the employees table:
After issuing the EXPLAIN PLAN statement, use a script or package provided by Oracle Database to display the most recent plan table output.
The following example uses the DBMS_XPLAN.DISPLAY function:
Review the plan output.
For example, the following plan shows a hash join:
The execution order in EXPLAIN PLAN output begins with the line that is the furthest indented to the right. The next step is the parent of that line. If two lines are indented equally, then the top line is normally executed first.
The steps in the EXPLAIN PLAN output in this chapter may be different on your database. The optimizer may choose different execution plans, depending on database configurations.
Oracle Database SQL Language Reference for the syntax and semantics of EXPLAIN PLAN
6.2.3 Specifying a Statement ID in EXPLAIN PLAN: Example
With multiple statements, you can specify a statement identifier and use that to identify your specific execution plan.
Before using SET STATEMENT ID , remove any existing rows for that statement ID. In the following example, st1 is specified as the statement identifier.
Example 6-1 Using EXPLAIN PLAN with the STATEMENT ID Clause
6.2.4 Specifying a Different Location for EXPLAIN PLAN Output: Example
The INTO clause of EXPLAIN PLAN specifies a different table in which to store the output.
If you do not want to use the name PLAN_TABLE , create a new synonym after running the catplan.sql script. For example:
The following statement directs output to my_plan_table :
You can specify a statement ID when using the INTO clause, as in the following statement:
«PLAN_TABLE Columns» for a description of the columns in PLAN_TABLE
6.2.5 EXPLAIN PLAN Output for a CONTAINERS Query: Example
The CONTAINERS clause can be used to query both user-created and Oracle-supplied tables and views. It enables you to query these tables and views across all containers.
The following example illustrates the output of an EXPLAIN PLAN for a query using the CONTAINERS clause.
At Row 8 of this plan, CONTAINERS is shown in the Operation column as the value CONTAINERS FULL . The Name column in the same row shows the argument to CONTAINERS .
A query using the CONTAINERS clause is partitioned by default. At Row 7 in the plan, the PX PARTITION LIST ITERATOR in the Operation column indicates that the query is partitioned. Iteration over containers is implemented in this partition iterator. On the same row, the Pstart and Pstop values 1 and 9 are derived from the con_id < 10 predicate in the query.
A query using the CONTAINERS clause uses parallel execution servers by default. In Row 1 of the plan above, PX COORDINATOR in the Operation column indicates that parallel execution servers will be used. Each container is assigned to a parallel execution process ( P00* ). When the parallel execution process executes the part of the query EXECUTION PLAN that corresponds to CONTAINERS FULL , then the process switches into the container it has been assigned to work on. It retrieves rows from the base object by executing a recursive SQL statement.
6.3 Displaying Execution Plans
The easiest way to display execution plans is to use DBMS_XPLAN display functions or V$ views.
6.3.1 About the Display of PLAN_TABLE Output
To display the plan table output, you can use either SQL scripts or the DBMS_XPLAN package.
After you have explained the plan, use the following SQL scripts or PL/SQL package provided by Oracle Database to display the most recent plan table output:
DBMS_XPLAN.DISPLAY table function
This function accepts options for displaying the plan table output. You can specify:
A plan table name if you are using a table different than PLAN_TABLE
A statement ID if you have set a statement ID with the EXPLAIN PLAN
A format option that determines the level of detail: BASIC , SERIAL , TYPICAL , and ALL
Examples of using DBMS_XPLAN to display PLAN_TABLE output are:
This script displays the plan table output for serial processing
This script displays the plan table output including parallel execution columns.
Oracle Database PL/SQL Packages and Types Reference for more information about the DBMS_XPLAN package
6.3.1.1 DBMS_XPLAN Display Functions
You can use the DBMS_XPLAN display functions to show plans.
The display functions accept options for displaying the plan table output. You can specify:
A plan table name if you are using a table different from PLAN_TABLE
A statement ID if you have set a statement ID with the EXPLAIN PLAN
A format option that determines the level of detail: BASIC , SERIAL , TYPICAL , ALL , and in some cases ADAPTIVE
Table 6-1 DBMS_XPLAN Display Functions
This table function displays the contents of the plan table.
In addition, you can use this table function to display any plan (with or without statistics) stored in a table as long as the columns of this table are named the same as columns of the plan table (or V$SQL_PLAN_STATISTICS_ALL if statistics are included). You can apply a predicate on the specified table to select rows of the plan to display.
The format parameter controls the level of the plan. It accepts the values BASIC , TYPICAL , SERIAL , and ALL .
This table function displays the contents of an execution plan stored in AWR.
The format parameter controls the level of the plan. It accepts the values BASIC , TYPICAL , SERIAL , and ALL .
This table function displays the explain plan of any cursor loaded in the cursor cache. In addition to the explain plan, various plan statistics (such as. I/O, memory and timing) can be reported (based on the V$SQL_PLAN_STATISTICS_ALL VIEWS ).
The format parameter controls the level of the plan. It accepts the values BASIC , TYPICAL , SERIAL , ALL , and ADAPTIVE . When you specify ADAPTIVE , the output includes:
The final plan. If the execution has not completed, then the output shows the current plan. This section also includes notes about run-time optimizations that affect the plan.
Recommended plan. In reporting mode, the output includes the plan that would be chosen based on execution statistics.
Dynamic plan. The output summarizes the portions of the plan that differ from the default plan chosen by the optimizer.
Reoptimization. The output displays the plan that would be chosen on a subsequent execution because of reoptimization.
The format parameter controls the level of the plan. It accepts the values BASIC , TYPICAL , SERIAL , ALL , and ADAPTIVE . When you specify ADAPTIVE , the output includes the default plan. For each dynamic subplan, the plan shows a list of the row sources from the original that may be replaced, and the row sources that would replace them.
If the format argument specifies the outline display, then the function displays the hints for each option in the dynamic subplan. If the plan is not an adaptive query plan, then the function displays the default plan. When you do not specify ADAPTIVE , the plan is shown as-is, but with additional comments in the Note section that show any row sources that are dynamic.
This table function displays one or more execution plans for the specified SQL handle of a SQL plan baseline.
This function uses plan information stored in the plan baseline to explain and display the plans. The plan_id stored in the SQL management base may not match the plan_id of the generated plan. A mismatch between the stored plan_id and generated plan_id means that it is a non-reproducible plan. Such a plan is deemed invalid and is bypassed by the optimizer during SQL compilation.
This table function displays the execution plan of a given statement stored in a SQL tuning set.
The format parameter controls the level of the plan. It accepts the values BASIC , TYPICAL , SERIAL , and ALL .
Oracle Database PL/SQL Packages and Types Reference to learn more about DBMS_XPLAN display functions
6.3.1.2 Plan-Related Views
You can obtain information about execution plans by querying dynamic performance and data dictionary views.
Table 6-2 Execution Plan Views
Lists statistics for cursors and contains one row for each child of the original SQL text entered.
Starting in Oracle Database 19c , V$SQL.QUARANTINED indicates whether a statement has been terminated by the Resource Manager because the statement consumed too many resources. Oracle Database records and marks the quarantined plans and prevents the execution of statements using these plans from executing. The AVOIDED_EXECUTIONS column indicates the number of executions attempted but prevented because of the quarantined statement.
Explains why a particular child cursor is not shared with existing child cursors. Each column identifies a specific reason why the cursor cannot be shared.
The USE_FEEDBACK_STATS column shows whether a child cursor fails to match because of reoptimization.
Contains the plan for every statement stored in the shared SQL area.
The view definition is similar to PLAN_TABLE . The view includes a superset of all rows appearing in all final plans. PLAN_LINE_ID is consecutively numbered, but for a single final plan, the IDs may not be consecutive.
As an alternative to EXPLAIN PLAN , you can display the plan by querying V$SQL_PLAN . The advantage of V$SQL_PLAN over EXPLAIN PLAN is that you do not need to know the compilation environment that was used to execute a particular statement. For EXPLAIN PLAN , you would need to set up an identical environment to get the same plan when executing the statement.
Provides the actual execution statistics for every operation in the plan, such as the number of output rows and elapsed time. All statistics, except the number of output rows, are cumulative. For example, the statistics for a join operation also includes the statistics for its two inputs. The statistics in V$SQL_PLAN_STATISTICS are available for cursors that have been compiled with the STATISTICS_LEVEL initialization parameter set to ALL .
Contains memory usage statistics for row sources that use SQL memory (sort or hash join). This view concatenates information in V$SQL_PLAN with execution statistics from V$SQL_PLAN_STATISTICS and V$SQL_WORKAREA .
V$SQL_PLAN_STATISTICS_ALL enables side-by-side comparisons of the estimates that the optimizer provides for the number of rows and elapsed time. This view combines both V$SQL_PLAN and V$SQL_PLAN_STATISTICS information for every cursor.
«Monitoring Database Operations» for information about the V$SQL_PLAN_MONITOR view
Oracle Database Reference for more information about V$SQL_PLAN views
Oracle Database Reference for information about the STATISTICS_LEVEL initialization parameter
6.3.2 Displaying Execution Plans: Basic Steps
The DBMS_XPLAN.DISPLAY function is a simple way to display an explained plan.
By default, the DISPLAY function uses the format setting of TYPICAL . In this case, the plan the most relevant information in the plan: operation id, name and option, rows, bytes and optimizer cost. Pruning, parallel and predicate information are only displayed when applicable.
To display an execution plan:
Start SQL*Plus or SQL Developer and log in to the session in which you explained the plan.
Query PLAN_TABLE using DBMS_XPLAN.DISPLAY .
Specify the query as follows:
Alternatively, specify the statement ID using the statement_id parameter:
Example 6-2 EXPLAIN PLAN for Statement ID ex_plan1
This example explains a query of employees that uses the statement ID ex_plan1 , and then queries PLAN_TABLE :
Sample output appears below:
Example 6-3 EXPLAIN PLAN for Statement ID ex_plan2
This example explains a query of employees that uses the statement ID ex_plan2 , and then displays the plan using the BASIC format:
Sample output appears below:
Oracle Database PL/SQL Packages and Types Reference for more information about the DBMS_XPLAN package
6.3.3 Displaying Adaptive Query Plans: Tutorial
The adaptive optimizer is a feature of the optimizer that enables it to adapt plans based on run-time statistics. All adaptive mechanisms can execute a final plan for a statement that differs from the default plan.
An adaptive query plan chooses among subplans during the current statement execution. In contrast, automatic reoptimization changes a plan only on executions that occur after the current statement execution.
You can determine whether the database used adaptive query optimization for a SQL statement based on the comments in the Notes section of plan. The comments indicate whether row sources are dynamic, or whether automatic reoptimization adapted a plan.
This tutorial assumes the following:
The STATISTICS_LEVEL initialization parameter is set to ALL .
The database uses the default settings for adaptive execution.
As user oe , you want to issue the following separate queries:
Before executing each query, you want to query DBMS_XPLAN.DISPLAY_PLAN to see the default plan, that is, the plan that the optimizer chose before applying its adaptive mechanism.
After executing each query, you want to query DBMS_XPLAN.DISPLAY_CURSOR to see the final plan and adaptive query plan.
SYS has granted oe the following privileges:
GRANT SELECT ON V_$SESSION TO oe
GRANT SELECT ON V_$SQL TO oe
GRANT SELECT ON V_$SQL_PLAN TO oe
GRANT SELECT ON V_$SQL_PLAN_STATISTICS_ALL TO oe
To see the results of adaptive optimization:
Start SQL*Plus, and then connect to the database as user oe .
For example, use the following statement:
View the plan in the cursor.
For example, run the following commands:
The following sample output has been reformatted to fit on the page. In this plan, the optimizer chooses a nested loops join. The original optimizer estimates are shown in the E-Rows column, whereas the actual statistics gathered during execution are shown in the A-Rows column. In the MERGE JOIN operation, the difference between the estimated and actual number of rows is significant.
Run the same query of orders that you ran in Step 2.
View the execution plan in the cursor by using the same SELECT statement that you ran in Step 3.
The following example shows that the optimizer has chosen a different plan, using a hash join. The Note section shows that the optimizer used statistics feedback to adjust its cost estimates for the second execution of the query, thus illustrating automatic reoptimization.
Query V$SQL to verify the performance improvement.
The following query shows the performance of the two statements (sample output included).
The second statement executed, which is child number 1 , used statistics feedback. CPU time, elapsed time, and buffer gets are all significantly lower.
Explain the plan for the query of order_items .
For example, use the following statement:
View the plan in the plan table.
For example, run the following statement:
Sample output appears below:
In this plan, the optimizer chooses a nested loops join.
Run the query that you previously explained.
For example, use the following statement:
View the plan in the cursor.
For example, run the following commands:
Sample output appears below. Based on statistics collected at run time (Step 4), the optimizer chose a hash join rather than the nested loops join. The dashes ( — ) indicate the steps in the nested loops plan that the optimizer considered but do not ultimately choose. The switch illustrates the adaptive query plan feature.
Oracle Database Reference to learn about the STATISTICS_LEVEL initialization parameter
6.3.4 Display Execution Plans: Examples
These examples show different ways of displaying execution plans.
6.3.4.1 Customizing PLAN_TABLE Output
If you have specified a statement identifier, then you can write your own script to query the PLAN_TABLE .
Start with and given STATEMENT_ID .
Use the CONNECT BY clause to walk the tree from parent to child, the join keys being STATEMENT_ID = PRIOR STATMENT_ID and PARENT_ID = PRIOR ID .
Use the pseudo-column LEVEL (associated with CONNECT BY ) to indent the children.
The NULL in the Rows column indicates that the optimizer does not have any statistics on the table. Analyzing the table shows the following:
You can also select the COST . This is useful for comparing execution plans or for understanding why the optimizer chooses one execution plan over another.
These simplified examples are not valid for recursive SQL.
6.3.4.2 Displaying Parallel Execution Plans: Example
Plans for parallel queries differ in important ways from plans for serial queries.
6.3.4.2.1 About EXPLAIN PLAN and Parallel Queries
Tuning a parallel query begins much like a non-parallel query tuning exercise by choosing the driving table. However, the rules governing the choice are different.
In the serial case, the best driving table produces the fewest numbers of rows after applying limiting conditions. The database joins a small number of rows to larger tables using non-unique indexes.
For example, consider a table hierarchy consisting of customer , account , and transaction .
Figure 6-1 A Table Hierarchy
In this example, customer is the smallest table, whereas transaction is the largest table. A typical OLTP query retrieves transaction information about a specific customer account. The query drives from the customer table. The goal is to minimize logical I/O, which typically minimizes other critical resources including physical I/O and CPU time.
For parallel queries, the driving table is usually the largest table. It would not be efficient to use parallel query in this case because only a few rows from each table are accessed. However, what if it were necessary to identify all customers who had transactions of a certain type last month? It would be more efficient to drive from the transaction table because no limiting conditions exist on the customer table. The database would join rows from the transaction table to the account table, and then finally join the result set to the customer table. In this case, the used on the account and customer table are probably highly selective primary key or unique indexes rather than the non-unique indexes used in the first query. Because the transaction table is large and the column is not selective, it would be beneficial to use parallel query driving from the transaction table.
Parallel operations include the following:
A PARALLEL_TO_SERIAL operation is always the step that occurs when the query coordinator consumes rows from a parallel operation. Another type of operation that does not occur in this query is a SERIAL operation. If these types of operations occur, then consider making them parallel operations to improve performance because they too are potential bottlenecks.
If the workloads in each step are relatively equivalent, then the PARALLEL_TO_PARALLEL operations generally produce the best performance.
A PARALLEL_COMBINED_WITH_PARENT operation occurs when the database performs the step simultaneously with the parent step.
If a parallel step produces many rows, then the QC may not be able to consume the rows as fast as they are produced. Little can be done to improve this situation.
The OTHER_TAG column in «PLAN_TABLE Columns»
6.3.4.2.2 Viewing Parallel Queries with EXPLAIN PLAN: Example
When using EXPLAIN PLAN with parallel queries, the database compiles and executes one parallel plan. This plan is derived from the serial plan by allocating row sources specific to the parallel support in the QC plan.
The table queue row sources ( PX Send and PX Receive ), the granule iterator, and buffer sorts, required by the two parallel execution server set PQ model, are directly inserted into the parallel plan. This plan is the same plan for all parallel execution servers when executed in parallel or for the QC when executed serially.
Example 6-4 Parallel Query Explain Plan
The following simple example illustrates an EXPLAIN PLAN for a parallel query:
One set of parallel execution servers scans EMP2 in parallel, while the second set performs the aggregation for the GROUP BY operation. The PX BLOCK ITERATOR row source represents the splitting up of the table EMP2 into pieces to divide the scan workload between the parallel execution servers. The PX SEND and PX RECEIVE row sources represent the pipe that connects the two sets of parallel execution servers as rows flow up from the parallel scan, get repartitioned through the HASH table queue, and then read by and aggregated on the top set. The PX SEND QC row source represents the aggregated values being sent to the QC in random (RAND) order. The PX COORDINATOR row source represents the QC or Query Coordinator which controls and schedules the parallel plan appearing below it in the plan tree.
6.3.4.3 Displaying Bitmap Index Plans: Example
Index row sources using bitmap indexes appear in the EXPLAIN PLAN output with the word BITMAP indicating the type of the index.
Example 6-5 EXPLAIN PLAN with Bitmap Indexes
In this example, the predicate c1=2 yields a bitmap from which a subtraction can take place. From this bitmap, the bits in the bitmap for c2=6 are subtracted. Also, the bits in the bitmap for c2 IS NULL are subtracted, explaining why there are two MINUS row sources in the plan. The NULL subtraction is necessary for semantic correctness unless the column has a NOT NULL constraint. The TO ROWIDS option generates the rowids necessary for the table access.
Queries using bitmap join index indicate the bitmap join index access path. The operation for bitmap join index is the same as bitmap index.
6.3.4.4 Displaying Result Cache Plans: Example
When your query contains the result_cache hint, the ResultCache operator is inserted into the execution plan.
For example, consider the following query:
To view the EXPLAIN PLAN for this query, use the following command:
The EXPLAIN PLAN output for this query should look similar to the following:
In this EXPLAIN PLAN , the ResultCache operator is identified by its CacheId , which is b06ppfz9pxzstbttpbqyqnfbmy . You can now run a query on the V$RESULT_CACHE_OBJECTS view by using this CacheId .
6.3.4.5 Displaying Plans for Partitioned Objects: Example
Use EXPLAIN PLAN to determine how Oracle Database accesses partitioned objects for specific queries.
Partitions accessed after pruning are shown in the PARTITION START and PARTITION STOP columns. The row source name for the range partition is PARTITION RANGE . For hash partitions, the row source name is PARTITION HASH .
A join is implemented using partial partition-wise join if the DISTRIBUTION column of the plan table of one of the joined tables contains PARTITION(KEY) . Partial partition-wise join is possible if one of the joined tables is partitioned on its join column and the table is parallelized.
A join is implemented using full partition-wise join if the partition row source appears before the join row source in the EXPLAIN PLAN output. Full partition-wise joins are possible only if both joined tables are equipartitioned on their respective join columns. Examples of execution plans for several types of partitioning follow.
6.3.4.5.1 Displaying Range and Hash Partitioning with EXPLAIN PLAN: Examples
This example illustrates pruning by using the emp_range table, which partitioned by range on hire_date .
Assume that the tables employees and departments from the Oracle Database sample schema exist.
For the first example, consider the following statement:
Oracle Database displays something similar to the following:
The database creates a partition row source on top of the table access row source. It iterates over the set of partitions to be accessed. In this example, the partition iterator covers all partitions (option ALL ), because a predicate was not used for pruning. The PARTITION_START and PARTITION_STOP columns of the PLAN_TABLE show access to all partitions from 1 to 5.
For the next example, consider the following statement:
In the previous example, the partition row source iterates from partition 4 to 5 because the database prunes the other partitions using a predicate on hire_date .
Finally, consider the following statement:
In the previous example, only partition 1 is accessed and known at compile time; thus, there is no need for a partition row source.
Oracle Database displays the same information for hash partitioned objects, except the partition row source name is PARTITION HASH instead of PARTITION RANGE . Also, with hash partitioning, pruning is only possible using equality or IN -list predicates.
6.3.4.5.2 Pruning Information with Composite Partitioned Objects: Examples
To illustrate how Oracle Database displays pruning information for composite partitioned objects, consider the table emp_comp . It is range-partitioned on hiredate and subpartitioned by hash on deptno .
For the first example, consider the following statement:
This example shows the plan when Oracle Database accesses all subpartitions of all partitions of a composite object. The database uses two partition row sources for this purpose: a range partition row source to iterate over the partitions, and a hash partition row source to iterate over the subpartitions of each accessed partition.
In the following example, the range partition row source iterates from partition 1 to 5, because the database performs no pruning. Within each partition, the hash partition row source iterates over subpartitions 1 to 3 of the current partition. As a result, the table access row source accesses subpartitions 1 to 15. In other words, the database accesses all subpartitions of the composite object.
In the previous example, only the last partition, partition 5, is accessed. This partition is known at compile time, so the database does not need to show it in the plan. The hash partition row source shows accessing of all subpartitions within that partition; that is, subpartitions 1 to 3, which translates into subpartitions 13 to 15 of the emp_comp table.
Now consider the following statement:
In the previous example, the predicate deptno=20 enables pruning on the hash dimension within each partition. Therefore, Oracle Database only needs to access a single subpartition. The number of this subpartition is known at compile time, so the hash partition row source is not needed.
Finally, consider the following statement:
The last two examples are the same, except that department_id = : dno replaces deptno=20 . In this last case, the subpartition number is unknown at compile time, and a hash partition row source is allocated. The option is SINGLE for this row source because Oracle Database accesses only one subpartition within each partition. In Step 2, both PARTITION _ START and PARTITION _ STOP are set to KEY . This value means that Oracle Database determines the number of subpartitions at run time.
6.3.4.5.3 Examples of Partial Partition-Wise Joins
In these examples, the PQ_DISTRIBUTE hint explicitly forces a partial partition-wise join because the query optimizer could have chosen a different plan based on cost in this query.
Example 6-6 Partial Partition-Wise Join with Range Partition
In the following example, the database joins emp_range_did on the partitioning column department_id and parallelizes it. The database can use a partial partition-wise join because the dept2 table is not partitioned. Oracle Database dynamically partitions the dept2 table before the join.
The execution plan shows that the table dept2 is scanned serially and all rows with the same partitioning column value of emp_range_did (department_id) are sent through a PART (KEY) , or partition key, table queue to the same parallel execution server doing the partial partition-wise join.
Example 6-7 Partial Partition-Wise Join with Composite Partition
In the following example, emp_comp is joined on the partitioning column and is parallelized, enabling use of a partial partition-wise join because dept2 is not partitioned. The database dynamically partitions dept2 before the join.
The plan shows that the optimizer selects partial partition-wise join from one of two columns. The PX SEND node type is PARTITION (KEY) and the PQ Distrib column contains the text PART (KEY) , or partition key. This implies that the table dept2 is re-partitioned based on the join column department_id to be sent to the parallel execution servers executing the scan of EMP_COMP and the join.
6.3.4.5.4 Example of Full Partition-Wise Join
In this example, emp_comp and dept_hash are joined on their hash partitioning columns, enabling use of a full partition-wise join.
The PARTITION HASH row source appears on top of the join row source in the plan table output.
The PX PARTITION HASH row source appears on top of the join row source in the plan table output while the PX PARTITION RANGE row source appears over the scan of emp_comp . Each parallel execution server performs the join of an entire hash partition of emp_comp with an entire partition of dept_hash .
6.3.4.5.5 Examples of INLIST ITERATOR and EXPLAIN PLAN
An INLIST ITERATOR operation appears in the EXPLAIN PLAN output if an index implements an IN -list predicate.
Consider the following statement:
The EXPLAIN PLAN output appears as follows:
The INLIST ITERATOR operation iterates over the next operation in the plan for each value in the IN -list predicate. The following sections describe the three possible types of IN -list columns for partitioned tables and indexes.
6.3.4.5.5.1 When the IN-List Column is an Index Column: Example
If the IN -list column empno is an index column but not a partition column, then the IN -list operator appears before the table operation but after the partition operation in the plan.
The KEY(INLIST) designation for the partition start and stop keys specifies that an IN -list predicate appears on the index start and stop keys.
6.3.4.5.5.2 When the IN-List Column is an Index and a Partition Column: Example
If empno is an indexed and a partition column, then the plan contains an INLIST ITERATOR operation before the partition operation.
6.3.4.5.5.3 When the IN-List Column is a Partition Column: Example
If empno is a partition column and no indexes exist, then no INLIST ITERATOR operation is allocated.
If emp_empno is a bitmap index, then the plan is as follows:
6.3.4.5.6 Example of Domain Indexes and EXPLAIN PLAN
You can use EXPLAIN PLAN to derive user-defined CPU and I/O costs for domain indexes.
EXPLAIN PLAN displays domain index statistics in the OTHER column of PLAN_TABLE . For example, assume table emp has user-defined operator CONTAINS with a domain index emp_resume on the resume column, and the index type of emp_resume supports the operator CONTAINS . You explain the plan for the following query:
The database could display the following plan:
6.4 Comparing Execution Plans
The plan comparison tool takes a reference plan and an arbitrary list of test plans and highlights the differences between them. The plan comparison is logical rather than line by line.
6.4.1 Purpose of Plan Comparison
The plan comparison report identifies the source of differences, which helps users triage plan reproducibility issues.
The plan comparison report is particularly useful in the following scenarios:
You want to compare the current plan of a query whose performance is regressing with an old plan captured in AWR.
A SQL plan baseline fails to reproduce the originally intended plan, and you want to determine the difference between the new plan and the intended plan.
You want to determine how adding a hint, changing a parameter, or creating an index will affect a plan.
You want to determine how a plan generated based on a SQL profile or by SQL Performance Analyzer differs from the original plan.
6.4.2 User Interface for Plan Comparison
You can use DBMS_XPLAN.COMPARE_PLANS to generate a report in text, XML, or HTML format.
Compare Plans Report Format
The report begins with a summary. The COMPARE PLANS REPORT section includes information such as the user who ran the report and the number of plans compared, as shown in the following example:
The COMPARISON DETAILS section of the report contains the following information:
The information includes the plan number, the plan source, plan attributes (which differ depending on the source), parsing schema, and SQL text.
This section displays the plan rows, including the predicates and notes.
This section summarizes the comparison findings, highlighting logical differences such as join order, join methods, access paths, and parallel distribution method. The findings start at number 1 . For findings that relate to a particular query block, the text starts with the name of the block. For findings that relate to a particular object alias, the text starts with the name of the query block and the object alias. The following
DBMS_XPLAN.PLAN_OBJECT_LIST Table Type
The plan_object_list type allows for a list of generic objects as input to the DBMS_XPLAN.COMPARE_PLANS function. The syntax is as follows:
The generic object abstracts the common attributes of plans from all plan sources. Every plan source is a subclass of the plan_object_list superclass. The following table summarizes the different plan sources. Note that when an optional parameter is null, it can correspond to multiple objects. For example, if you do not specify a child number for cursor_cache_object , then it matches all cursor cache statements with the specified SQL ID.
Table 6-3 Plan Sources for PLAN_OBJECT_LIST
The parameters are as follows:
owner —The owner of the plan table
plan_table_name —The name of the plan table
statement_id —The ID of the statement (optional)
plan_id —The ID of the plan (optional)
The parameters are as follows:
sql_id —The SQL ID of the plan
child_number —The child number of the plan in the cursor cache (optional)
The parameters are as follows:
sql_id —The SQL ID of the plan
dbid —The database ID (optional)
con_dbid —The CDB ID (optional)
plan_hash_value —The hash value of the plan (optional)
The parameters are as follows:
sqlset_owner —The owner of the SQL tuning set
sqlset_name —The name of the SQL tuning set
sql_id —The SQL ID of the plan
plan_hash_value —The hash value of the plan (optional)
SQL plan management
The parameters are as follows:
sql_handle —The SQL handle of plans protected by SQL plan management
plan_name —The name of the SQL plan baseline (optional)
The profile_name parameter specifies the name of the SQL profile.
The parameters are as follows:
task_name —The name of the advisor task
execution_name —The name of the task execution
sql_id —The SQL ID of the plan
plan_id —The advisor plan ID (optional)
The interface for the compare plan tools is the following function:
The following table describes the parameters that specify that plans to be compared.
Table 6-4 Parameters for the COMPARE_PLANS Function
Specifies a single plan of type generic_plan_object .
Specifies a list of plan objects. An object might correspond to one or more plans.
Example 6-8 Comparing Plans from Child Cursors
This example compares the plan of child cursor number 2 for the SQL ID 8mkxm7ur07za0 with the plan for child cursor number 4 for the same SQL ID.
Example 6-9 Comparing Plan from Child Cursor with Plan from SQL Plan Baseline
This example compares the plan of child cursor number 2 for the SQL ID 8mkxm7ur07za0 with the plan from the SQL plan baseline. The baseline query has a SQL handle of SQL_024d0f7d21351f5d and a plan name of SQL_PLAN_sdfjkd .
Example 6-10 Comparing a Plan with Plans from Multiple Sources
This example prints the summary section only. The program compares the plan of child cursor number 2 for the SQL ID 8mkxm7ur07za0 with every plan in the following list:
All plans in the shared SQL area that are generated for the SQL ID 8mkxm7ur07za0
All plans generated in the SQL tuning set SH. SQLT_WORKLOAD for the SQL ID 6vfqvav0rgyad
All plans in AWR that are captured for database ID 5 and SQL ID 6vfqvav0rgyad
The plan baseline for the query with handle SQL_024d0f7d21351f5d with name SQL_PLAN_sdfjkd
The plan stored in sh.plan_table identified by plan_id=38
The plan identified by the SQL profile name pe3r3ejsfd
All plans stored in SQL advisor identified by task name TASK_1228 , execution name EXEC_1928 , and SQL ID 8mkxm7ur07za0
Oracle Database PL/SQL Packages and Types Reference for more information about the DBMS_XPLAN package
6.4.3 Comparing Execution Plans: Tutorial
To compare plans, use the DBMS_XPLAN.COMPARE_PLANS function.
This tutorial assumes that user sh issued the following queries:
To compare execution plans:
Start SQL*Plus, and log in to the database with administrative privileges.
Query V$SQL to determine the SQL IDs of the two queries.
The following query queries V$SQL for queries that contain the string products :
Log in to the database as user sh .
Execute the DBMS_XPLAN.COMPARE_PLANS function, specifying the SQL IDs obtained in the previous step.
For example, execute the following program:
Print the report.
For example, run the following query:
The Comparison Results section of the following sample report shows that only the first query used a join elimination transformation:
Oracle Database PL/SQL Packages and Types Reference for more information about the DBMS_XPLAN package
6.4.4 Comparing Execution Plans: Examples
These examples demonstrate how to generate compare plans reports for queries of tables in the sh schema.
Example 6-11 Comparing an Explained Plan with a Plan in a Cursor
This example explains a plan for a query of tables in the sh schema, and then executes the query:
Assume that the SQL ID of the executed query is 9mp7z6qq83k5y . The following PL/SQL program compares the plan in PLAN_TABLE and the plan in the shared SQL area:
The following sample report shows that the plans are the same:
Example 6-12 Comparing Plans in a Baseline and SQL Tuning Set
Assume that you want to compare the plans for the following queries, which differ only in the NO_MERGE hint contained in the subquery:
The plan for the first query is captured in a SQL plan management baseline with SQL handle SQL_c522f5888cc4613e . The plan for the second query is stored in a SQL tuning set named MYSTS1 and has a SQL ID of d07p7qmrm13nc . You run the following PL/SQL program to compare the plans:
The following output shows that the only the reference plan, which corresponds to the query without the hint, used a view merge:
Example 6-13 Comparing Plans Before and After Adding an Index
In this example, you test the effect of an index on a query plan:
You execute the following PL/SQL program to generate the report:
The following report indicates that the operations in the two plans are different:
Example 6-14 Comparing Plans with Visible and Invisible Indexes
In this example, an application executes the following query:
The plan for this query uses two indexes: sales_prod_bix and products_prod_status_bix . The database generates four plans, using all combinations of visible and invisible for both indexes. Assume that SQL plan management accepts the following plans in the baseline for the query:
sales_prod_bix visible and products_prod_status_bix visible
sales_prod_bix visible and products_prod_status_bix invisible
sales_prod_bix invisible and products_prod_status_bix visible
You make both indexes invisible, and then execute the query again. The optimizer, unable to use the invisible indexes, generates a new plan. The three baseline plans, all of which rely on at least one index being visible, fail to reproduce. Therefore, the optimizer uses the new plan and adds it to the SQL plan baseline for the query. To compare the plan currently in the shared SQL area, which is the reference plan, with all four plans in the baseline, you execute the following PL/SQL code:
The following report compares all five plans:
The preceding report shows the following:
Plan 1 is the reference plan from the shared SQL area. The plan does not use the indexes, which are both invisible, and does not reproduce a baseline plan.
Plan 2 is in the baseline and assumes sales_prod_bix is invisible and products_prod_status_bix is visible.
Plan 3 is in the baseline and assumes both indexes are invisible. Plan 1 and Plan 3 are the same.
Plan 4 is in the baseline and assumes sales_prod_bix is visible and products_prod_status_bix is invisible.
Plan 5 is in the baseline and assumes that both indexes are visible.
The comparison report shows that Plan 1 could not reproduce a plan from that baseline. The reason is that the plan in the cursor (Plan 1) was added to the baseline because no baseline plan was available at the time of execution, so the database performed a soft parse of the statement and generated the no-index plan. If the current cursor were to be invalidated, and if the query were to be executed again, then a comparison report would show that the cursor plan did reproduce a baseline plan.
Oracle Database PL/SQL Packages and Types Reference for more information about the DBMS_XPLAN package
Example 6-15 Comparing a Baseline That Fails to Reproduce
One use case is to compare a cost-based plan with a SQL plan baseline. In this example, you create a unique index. The database captures a plan baseline that uses this index. You then make the index invisible and execute the query again. The baseline plan fails to reproduce because the index is not visible, forcing the optimizer to choose a different plan. A compare plans report between the baseline plan and the cost-based plan shows the difference in the access path between the two plans.
Log in to the database as user hr , and then create a plan table:
Execute the following DDL statements, which create a table named staff and an index on the staff.employee_id column:
Execute the following statements to place a query of staff under the protection of SQL Plan Management, and then make the index invisible:
Explain the plan, and then query the plan table (sample output included):
As the preceding output shows, the optimizer chooses a full table scan because the index is invisible. Because the SQL plan baseline uses an index, the optimizer cannot reproduce the plan.
In a separate session, log in as SYS and query the handle and plan name of the SQL plan baseline (sample output included):
Compare the plans, specifying the SQL handle and plan baseline name obtained from the previous step:
Как читать план исполнения запроса SQL в Oracle
Исполнение любого SQL предложения в Oracle извлекает так называемый «план исполнения». Этот план исполнения запроса является описанием того, как Oracle будет осуществялть выборку данных, согласно исполняемому SQL предложению. План представляет собой дерево, которое содержит порядок шагов и связь между ними.
Базовые правила плана исполнения:
- План исполнения имеет корень, ветвь не имеющую родителя
- Родительские ветки могут иметь одного и более потомков, и их идентификатор меньше чем идентификатор потомка
- У потомка может быть только один родитель, это справедливо и для нескольких уровней вложенности
Приведем пример плана исполнения:
Если следовать перечисленным выше правилам, то:
- Операция 0 — корень дерева, и у нее один потомок, операция 1
- У операции 1 два потомка — операции 2 и 4
- У операции 2 один потомок — операция 3
Если представить это графически, то получиться примерно так:
Если прочитать это дерево, то получим следующее, в порядке выполнения: Для выполнения операции 1, необходимо выполнить операции 2 и 4. Операция 2 выполняется первой. Во время выполнения операции 2, необходимо выполнить операцию 3. Для выполнения операции 4, необходимо выполнить операцию 2.