Что такое оконные функции в sql
MySQL 8.0 Reference Manual Including MySQL NDB Cluster 8.0
12.20.2 Window Function Concepts and Syntax
This section describes how to use window functions. Examples use the same sales information data set as found in the discussion of the GROUPING() function in Section 12.19.2, “GROUP BY Modifiers”:
A window function performs an aggregate-like operation on a set of query rows. However, whereas an aggregate operation groups query rows into a single result row, a window function produces a result for each query row:
The row for which function evaluation occurs is called the current row.
The query rows related to the current row over which function evaluation occurs comprise the window for the current row.
For example, using the sales information table, these two queries perform aggregate operations that produce a single global sum for all rows taken as a group, and sums grouped per country:
By contrast, window operations do not collapse groups of query rows to a single output row. Instead, they produce a result for each row. Like the preceding queries, the following query uses SUM() , but this time as a window function:
Each window operation in the query is signified by inclusion of an OVER clause that specifies how to partition query rows into groups for processing by the window function:
The first OVER clause is empty, which treats the entire set of query rows as a single partition. The window function thus produces a global sum, but does so for each row.
The second OVER clause partitions rows by country, producing a sum per partition (per country). The function produces this sum for each partition row.
Window functions are permitted only in the select list and ORDER BY clause. Query result rows are determined from the FROM clause, after WHERE , GROUP BY , and HAVING processing, and windowing execution occurs before ORDER BY , LIMIT , and SELECT DISTINCT .
The OVER clause is permitted for many aggregate functions, which therefore can be used as window or nonwindow functions, depending on whether the OVER clause is present or absent:
MySQL also supports nonaggregate functions that are used only as window functions. For these, the OVER clause is mandatory:
For details about each nonaggregate function, see Section 12.20.1, “Window Function Descriptions”.
As an example of one of those nonaggregate window functions, this query uses ROW_NUMBER() , which produces the row number of each row within its partition. In this case, rows are numbered per country. By default, partition rows are unordered and row numbering is nondeterministic. To sort partition rows, include an ORDER BY clause within the window definition. The query uses unordered and ordered partitions (the row_num1 and row_num2 columns) to illustrate the difference between omitting and including ORDER BY :
As mentioned previously, to use a window function (or treat an aggregate function as a window function), include an OVER clause following the function call. The OVER clause has two forms:
Both forms define how the window function should process query rows. They differ in whether the window is defined directly in the OVER clause, or supplied by a reference to a named window defined elsewhere in the query:
In the first case, the window specification appears directly in the OVER clause, between the parentheses.
In the second case, window_name is the name for a window specification defined by a WINDOW clause elsewhere in the query. For details, see Section 12.20.4, “Named Windows”.
For OVER ( window_spec ) syntax, the window specification has several parts, all optional:
If OVER() is empty, the window consists of all query rows and the window function computes a result using all rows. Otherwise, the clauses present within the parentheses determine which query rows are used to compute the function result and how they are partitioned and ordered:
window_name : The name of a window defined by a WINDOW clause elsewhere in the query. If window_name appears by itself within the OVER clause, it completely defines the window. If partitioning, ordering, or framing clauses are also given, they modify interpretation of the named window. For details, see Section 12.20.4, “Named Windows”.
partition_clause : A PARTITION BY clause indicates how to divide the query rows into groups. The window function result for a given row is based on the rows of the partition that contains the row. If PARTITION BY is omitted, there is a single partition consisting of all query rows.
Partitioning for window functions differs from table partitioning. For information about table partitioning, see Chapter 24, Partitioning.
partition_clause has this syntax:
Standard SQL requires PARTITION BY to be followed by column names only. A MySQL extension is to permit expressions, not just column names. For example, if a table contains a TIMESTAMP column named ts , standard SQL permits PARTITION BY ts but not PARTITION BY HOUR(ts) , whereas MySQL permits both.
order_clause : An ORDER BY clause indicates how to sort rows in each partition. Partition rows that are equal according to the ORDER BY clause are considered peers. If ORDER BY is omitted, partition rows are unordered, with no processing order implied, and all partition rows are peers.
order_clause has this syntax:
Each ORDER BY expression optionally can be followed by ASC or DESC to indicate sort direction. The default is ASC if no direction is specified. NULL values sort first for ascending sorts, last for descending sorts.
An ORDER BY in a window definition applies within individual partitions. To sort the result set as a whole, include an ORDER BY at the query top level.
frame_clause : A frame is a subset of the current partition and the frame clause specifies how to define the subset. The frame clause has many subclauses of its own. For details, see Section 12.20.3, “Window Function Frame Specification”.
SQL window functions
This article is an introduction to the basics of window functions in SQL. First, in the introduction, I will explain what is a window function and what it does. Then, I will show you how to write window functions. Finally, I will go through the different types of window functions we can use. At the end of the article, I will link to some practical examples of how we can use those functions. More examples will be added later as I write more articles on the topic.
Introduction
A window function performs calculations against a partition of the data. The two main characteristics of window functions are: — They don’t collapse rows of a group — They can run calculations on a set of rows related to the current row.
Let’s see what it means.
- Window functions don’t collapse rows of a group. The difference with aggregation functions using the GROUP BY clause is that the result is not grouped into single rows. Instead, the resultset contains every row of each group. To illustrate, we’ll write queries that sum the salaries of each department of a company.
Aggregation functions return a single result per group, hiding the rows of each group.
When using a window function, all the rows of each group are returned.
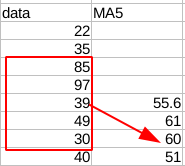
- Window functions can run calculations on a set of rows related to the current row. Window functions can run their calculation on a window that ‘slides’ along the dataset. It can include a number of rows before and/or after the current row. A common example of such operation is how we calculate a moving average. For example, a 5 periods moving average will only include the last five rows: In the example below, \(60 = \frac<85+97+39+49+30><5>\) .
Syntax
A window function call always contains an OVER clause. The OVER clause is what defines the window partitions.
The OVER() clause
The OVER() clause is where the partitionning of the window function is set. It contains three clauses: — PARTITION BY — ORDER BY — ROWS or RANGE
PARTITION BY
Splits the table into partitions based on a column’s unique values.
Let’s have a look at salaries:
If I write the following query,
I get a unique row with the highest of all salaries:
If I want to get the maximum salary for each department, I can use the PARTITION BY department clause:
For each row, I get the maximum salary for that department. For example, we can see that Shelley Higgins has the highest salary in the Accounting department.
ORDER BY
Specifies the order of rows in a partition. From the previous example, we can order the rows by employee:
We now have the departments that are grouped together and all employees of a department are sorted alphabetically.
ROWS or RANGE
The last clause defines the frame. This is a subset of rows against which the function is run.
It can either specify where the frame starts only:
Or it can specify where the frame starts and where it ends:
frame_start is one of the following options: — N PRECEDING: N rows before the current row. — UNBOUNDED PRECEDING: all the rows preceding the current row. — CURRENT ROW
frame_end is one of the following options: — CURRENT ROW — N FOLLOWING: N rows after the current row. — UNBOUNDED FOLLOWING: all the rows following the current row.
Setting up the frame start only:
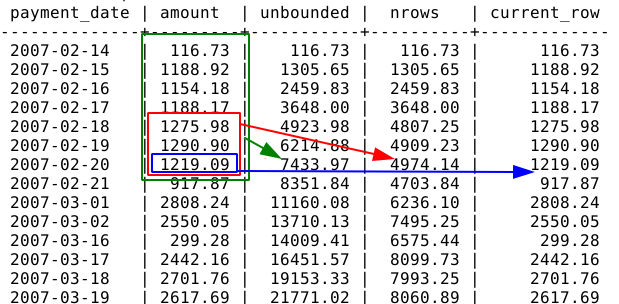
Let’s look at some example using BETWEEN . AND . :
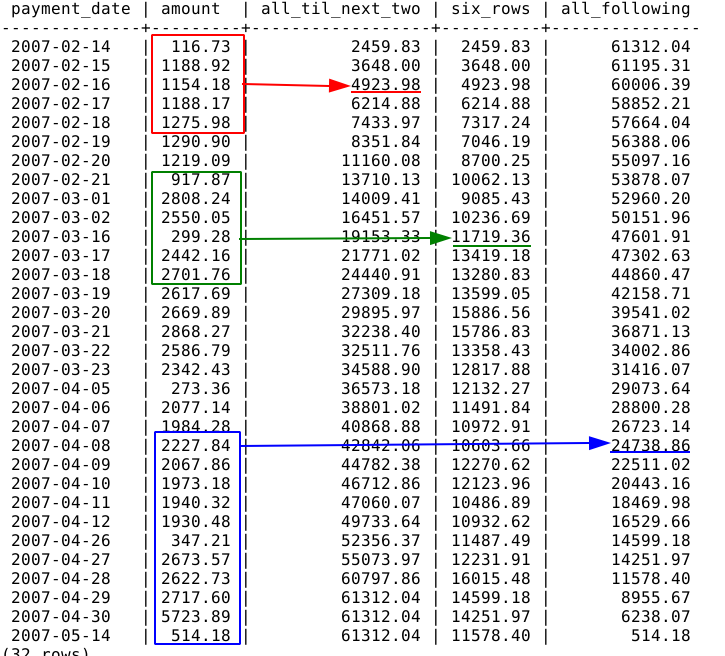
The BETWEEN UNBOUNDED PRECEDING AND 2 FOLLOWING clause will sum all the amounts from the beginning (UNBOUNDED PRECEDING) until two rows after the current row (2 FOLLOWING) as shown by the red frame.
The BETWEEN 3 PRECEDING AND 2 FOLLOWING clause will sum all the amounts from three rows before the current row (3 PRECEDING) until two rows after the current row (2 FOLLOWING) as shown by the green frame.
Finally, the BETWEEN CURRENT ROW AND UNBOUNDED FOLLOWING clause will sum all the amounts from the current row to the last row (UNBOUNDED FOLLOWING) as shown by the blue frame.
What is the difference between ROWS and RANGE To check the difference between ROWS and RANGE, I am going to write a query that sums the salaries using each of the frames keywords:
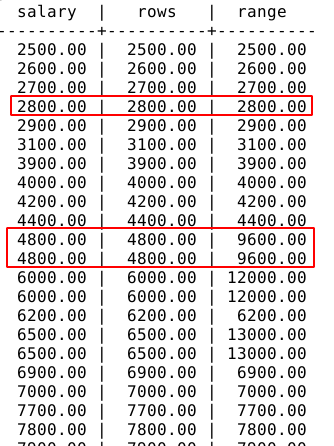
We can see there’s a difference when there are duplicate values. RANGE returns all rows with the same value as a unique current row. In our example, there are two employees with a salary of 4800. When using ROWS, the sum returns 4800 for each of the rows. When using RANGE, the sum returns 9600 (4800 + 4800) on both rows.
Window functions types
Value window functions
The value window functions return the value of a column or expression at a specified row of a resultset.
FIRST_VALUE()
The FIRST_VALUE() function returns the first value in a sorted partition.
syntax:
Example: Let’s write a query that gives us the name of the employee who has the lowest salary of each department. We’ll build the window function as follow: — partition the data by department: PARTITION BY department . — order the salaries to get the lowest one in the first row of the partition: ORDER BY salary . — get the name of the employee in the first row of the partition: FIRST_VALUE(employee) .
The final query will look like this:
LAST_VALUE()
The LAST_VALUE() function returns the value of the last row of the partition. Unlike the FIRST_VALUE() function, it requires that the frame is specified in the OVER() clause.
Syntax:
Example:
We can use the same example we used for the first_value() function. This time, we want to see who has the highest salary in each department: — partition the data by department: PARTITION BY department . — order the salaries to get the highest one in the last row of the partition: ORDER BY salary . — get the name of the employee in the last row of the partition: LAST_VALUE(employee) .
The LAG() funciton accesses the row that is n rows before the current row. We can also set a default value that will be returned when the row does not exist.
Syntax:
where offset is the number of rows before the current row from which we want the data.
Example:
We can use the LAG() function to compare daily sales with the previous week sales. To do so, we: — order the sales by date: ORDER BY payment_date . — get the amount from 7 days before: LAG(amount, 7) . — we can add a default value for the first 7 rows: LAG(amount, 7, 0::numeric ).
The final query looks like this:
The LEAD() function is similar to the LAG() but it returns the value of the nth row following the current row.
Syntax:
Example:
We can write a query that gives us the sales of the next week: — order the sales by date: ORDER BY payment_date . — get the amount 7 days after the date of the current row: LEAD(amount, 7) .
NTH_VALUE()
The NTH_VALUE() returns the value from the Nth row of a partition.
Syntax:
- expression: the target column or an expression.
- offset: integer that determines the row number relative to the first row of the partition.
Example:
For this example, I’ll simply write a query that gives the third salary from the lowest one for each department: — Group the salaries per department: PARTITION BY department . — Order the salaries: ORDER BY salary . — Get the third salary: NTH_VALUE(salary, 3) .
When the total number of rows of a partition is less than the offset, the NTH_VALUE() function returns a Null value.
Ranking window functions
ROW_NUMBER()
the ROW_NUMBER() function returns the number of the current row within its partition.
Syntax:
Example:
CUME_DIST()
The CUME_DIST() function calculate the cumulative distribution of a value. This is the number of rows with values less or equal to the value of the current row divided by the total number of rows.
Syntax:
Example:
In the example above, we can see that 20% of employees have a salary that is less or equal to 4000.
RANK and DENSE_RANK()
The RANK() and the DENSE_RANK() functions return the rank of the current row. The difference is that the DENSE_RANK() function result has no gap while the RANK() function will skip ranks when rows have the same values.
Syntax:
— DENSE_RANK()
- RANK()
Example:
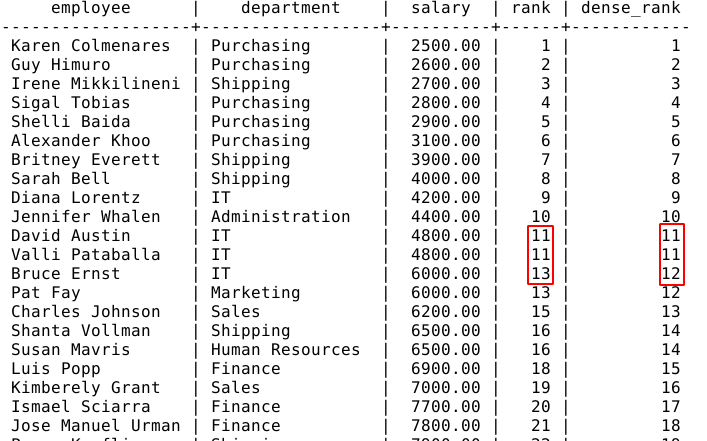
In the example above, we can see that there are two employees with a salary of 4,800. Both of them get the rank 11 in the rank and the dense_rank columns. However, the following employee’s rank is 13 in the rank column and 12 in the dense_rank columns. The DENSE_RANK() function didn’t skip any value. The RANK() returns the actual row number of the first row with a given value.
PERCENT_RANK()
The PERCENT_RANK() function returns the relative rank of the current row:
The values range from 0 to 1.
Syntax:
Example:
NTILE()
The NTILE() function breaks a resultset into a specified number of buckets. All the buckets have about the same number of rows.
Syntax:
Example:
We have 40 employees. The NTILE(4) columns returns four buckets numbered 1 to 4 and containing ten employees each. The NTILE(10) column returns 10 buckets numbered 1 to 10 and containing four employees each.
Aggregate window functions
Those are the usual aggregate functions we would use with a GROUP BY clause: — AVG(): average. — SUM(): sum. — MIN(): minimum value. — MAX(): maximum value. — COUNT(): rows count.
Оконные функции в SQL — что это и зачем они нужны
Многие разработчики, даже давно знакомые с SQL, не понимают оконные функции, считая их какой-то особой магией для избранных. И, хотя реализация оконных функций поддерживается с SQL Server 2005, кто-то до сих пор «копипастит» их со StackOverflow, не вдаваясь в детали. Этой статьёй мы попытаемся развенчать миф о неприступности этой функциональности SQL и покажем несколько примеров работы оконных функций на реальном датасете.
Почему не GROUP BY и не JOIN
Сразу проясним, что оконные функции — это не то же самое, что GROUP BY. Они не уменьшают количество строк, а возвращают столько же значений, сколько получили на вход. Во-вторых, в отличие от GROUP BY, OVER может обращаться к другим строкам. И в-третьих, они могут считать скользящие средние и кумулятивные суммы.
[badge style=»blue»]Примечание[/badge] Оконные функции не изменяют выборку, а только добавляют некоторую дополнительную информацию о ней. Для простоты понимания можно считать, что SQL сначала выполняет весь запрос (кроме сортировки и limit), а уже потом считает значения окна.
Окей, с GROUP BY разобрались. Но в SQL практически всегда можно пойти несколькими путями. К примеру, может возникнуть желание использовать подзапросы или JOIN. Конечно, JOIN по производительности предпочтительнее подзапросов, а производительность конструкций JOIN и OVER окажется одинаковой. Но OVER даёт больше свободы, чем жёсткий JOIN. Да и объём кода в итоге окажется гораздо меньше.
Для начала
Оконные функции начинаются с оператора OVER и настраиваются с помощью трёх других операторов: PARTITION BY, ORDER BY и ROWS. Про ORDER BY, PARTITION BY и его вспомогательные операторы LAG, LEAD, RANK мы расскажем подробнее.
Все примеры будут основаны на датасете олимпийских медалистов от Datacamp. Таблица называется summer_medals и содержит результаты Олимпиад с 1896 по 2010: 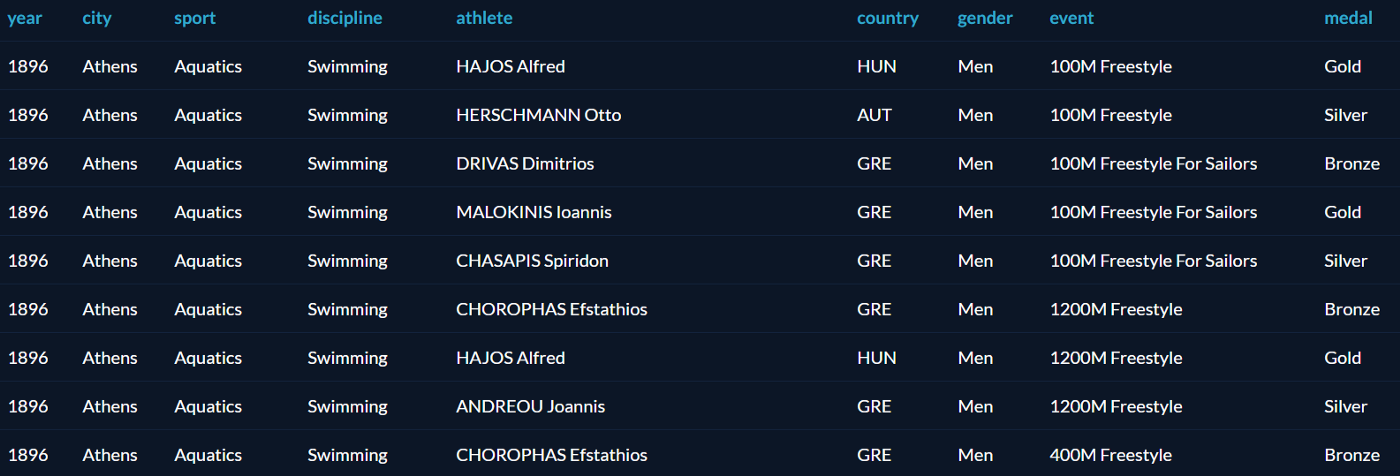
ROW_NUMBER и ORDER BY
Как уже говорилось выше, оператор OVER создаёт оконную функцию. Начнём с простой функции ROW_NUMBER, которая присваивает номер каждой выбранной записи:
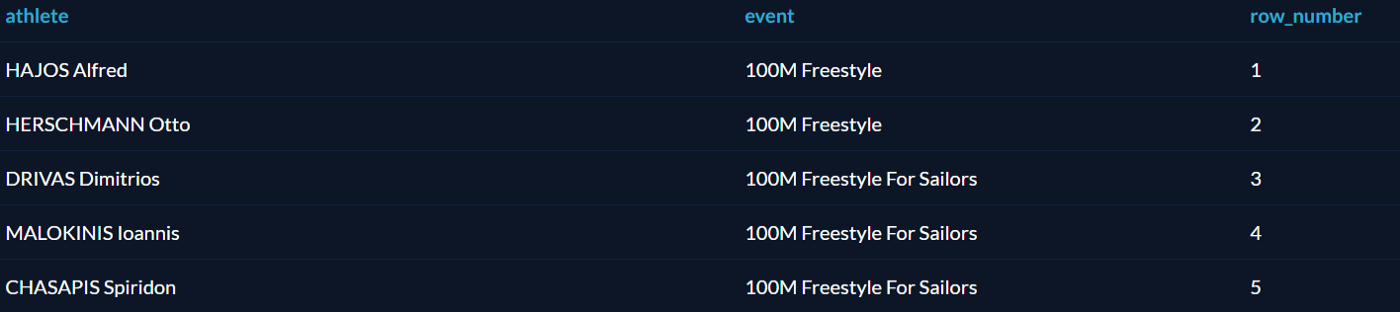
Каждая пара «спортсмен — вид спорта» получила номер, причём к этим номерам можно обращаться по имени row_number.
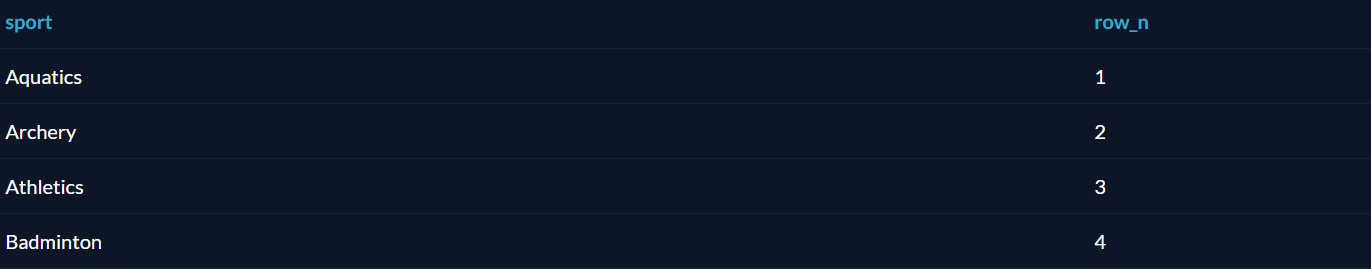
ROW_NUMBER можно объединить с ORDER BY, чтобы определить, в каком порядке строки будут нумероваться. Выберем с помощью DISTINCT все имеющиеся виды спорта и пронумеруем их в алфавитном порядке:
PARTITION BY и LAG, LEAD и RANK
PARTITION BY позволяет сгруппировать строки по значению определённого столбца. Это полезно, если данные логически делятся на какие-то категории и нужно что-то сделать с данной строкой с учётом других строк той же группы (скажем, сравнить теннисиста с остальными теннисистами, но не с бегунами или пловцами). Этот оператор работает только с оконными функциями типа LAG, LEAD, RANK и т. д.
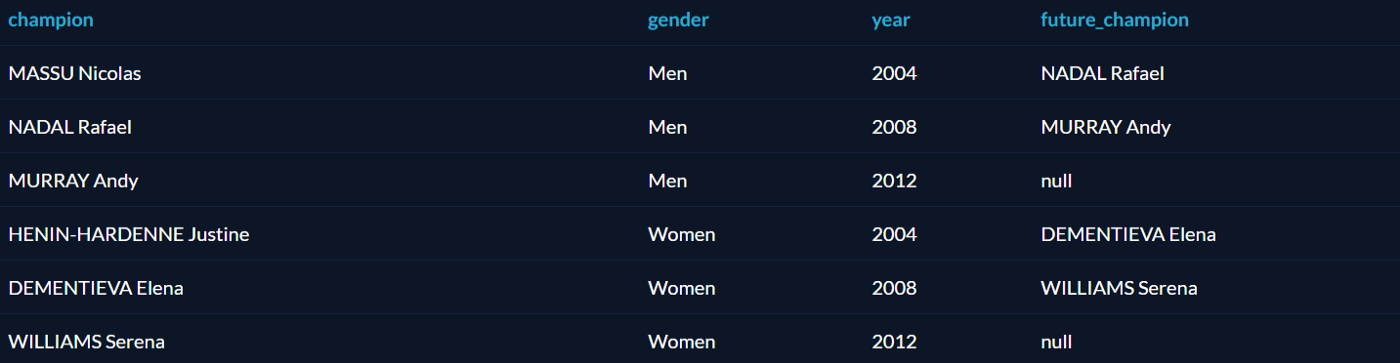
Функция LAG берёт строку и возвращает ту, которая шла перед ней. Например, мы хотим найти всех олимпийских чемпионов по теннису (мужчин и женщин отдельно), начиная с 2004 года, и для каждого из них выяснить, кто был предыдущим чемпионом.
Решение этой задачи требует нескольких шагов. Сначала надо создать табличное выражение, которое сохранит результат запроса «чемпионы по теннису с 2004 года» как временную именованную структуру для дальнейшего анализа. А затем разделить их по полу и выбрать предыдущего чемпиона с помощью LAG:

Функция PARTITION BY в таблице вернула сначала всех мужчин, потом всех женщин. Для победителей 2008 и 2012 года приведён предыдущий чемпион; так как данные есть только за 3 олимпиады, у чемпионов 2004 года нет предшественников, поэтому в соответствующих полях стоит null.
Функция LEAD похожа на LAG, но вместо предыдущей строки возвращает следующую. Можно узнать, кто стал следующим чемпионом после того или иного спортсмена:
Оператор RANK похож на ROW_NUMBER, но присваивает одинаковые номера строкам с одинаковыми значениями, а «лишние» номера пропускает. Есть также DENSE_RANK, который не пропускает номеров. Звучит запутанно, так что проще показать на примере. Вот ранжирование стран по числу олимпиад, в которых они участвовали, разными операторами:
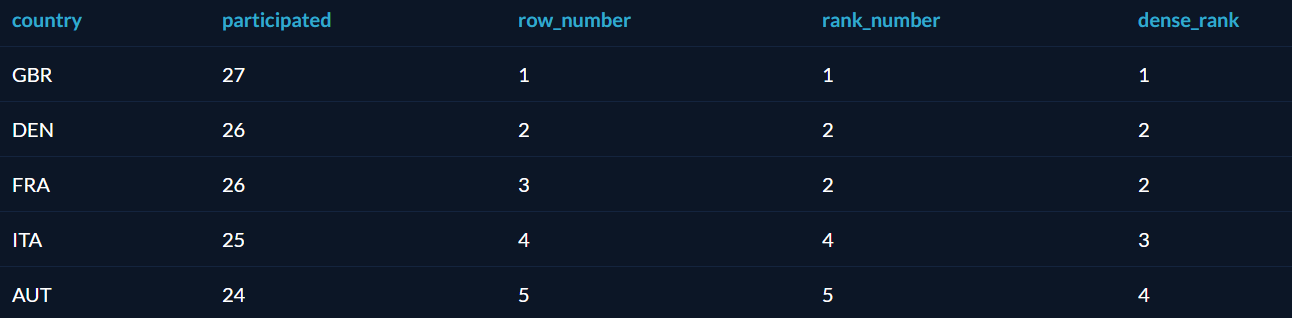
- Row_number — ничего интересного, строки просто пронумерованы по возрастанию.
- Rank_number — строки ранжированы по возрастанию, но нет номера 3. Вместо этого, 2 строки делят номер 2, а за ними сразу идёт номер 4.
- Dense_rank — то же самое, что и rank_number, но номер 3 не пропущен. Номера идут подряд, но зато никто не оказался пятым из пяти.
Напоследок
Вот так мы и разложили этот датасет по полочкам при помощи оконных функций. На этом наше введение в оконные функции заканчивается. Надеемся, это было интересно и не так сложно, как могло показаться.
Конечно, это далеко не все возможности оконных функций. Для них есть много других полезных вещей, например ROWS, NTILE и агрегирующие функции (SUM, MAX, MIN и другие), но об этом поговорим в другой раз.
Оконные функции SQL простым языком с примерами
Сразу хочется отметить, что данная статья написана исключительно для людей, начинающих свой путь в изучении SQL и оконных функций. Здесь могут быть не разобраны сложные применения функций и могут не использоваться сложные формулировки определений — все написано максимально простым языком для базового понимания.
P.S. Если автор что-то не разобрал и не написал, значит он посчитал это не обязательным в рамках этой статьи)))
Для примеров будем использовать небольшую таблицу, которая показывает оценки учеников по разным предметам. В БД табличка выглядит следующим образом

SQL часто используется для вычислений в данных различных метрик или агрегаций значений по измерениям. Помимо функций агрегации для этого широко используются оконные функции.
Оконная функция в SQL — функция, которая работает с выделенным набором строк (окном, партицией) и выполняет вычисление для этого набора строк в отдельном столбце.
Партиции (окна из набора строк) — это набор строк, указанный для оконной функции по одному из столбцов или группе столбцов таблицы. Партиции для каждой оконной функции в запросе могут быть разделены по различным колонкам таблицы.

В чем заключается главное отличие оконных функций от функций агрегации с группировкой?
При использовании агрегирующих функций предложение GROUP BY сокращает количество строк в запросе с помощью их группировки.

При использовании оконных функций количество строк в запросе не уменьшается по сравнении с исходной таблицей.

Порядок расчета оконных функций в SQL запросе

Сначала выполняется команда выборки таблиц, их объединения и возможные подзапросы под командой FROM.
Далее выполняются условия фильтрации WHERE, группировки GROUP BY и возможная фильтрация c HAVING
Только потом применяется команда выборки столбцов SELECT и расчет оконных функций под выборкой.
После этого идет условие сортировки ORDER BY, где тоже можно указать столбец расчета оконной функции для сортировки.
Здесь важно уточнить, что партиции или окна оконных функций создаются после разделения таблицы на группы с помощью команды GROUP BY, если эта команда используется в запросе.
Синтаксис оконных функций
Синтаксис оконных функций вне зависимости от их класса будет так или иначе состоять из идентичных команд.

Оконные функции можно прописывать как под командой SELECT, так и в отдельном ключевом слове WINDOW, где окну дается алиас (псевдоним), к которому можно обращаться в SELECT выборке.

Классы Оконных функций
Множество оконных функций можно разделять на 3 класса:
Функции смещения (Value)
Агрегирующие:
Можно применять любую из агрегирующих функций — SUM, AVG, COUNT, MIN, MAX

Ранжирующие:
В ранжирующих функция под ключевым словом OVER обязательным идет указание условия ORDER BY, по которому будет происходить сортировка ранжирования.
ROW_NUMBER() — функция вычисляет последовательность ранг (порядковый номер) строк внутри партиции, НЕЗАВИСИМО от того, есть ли в строках повторяющиеся значения или нет.
RANK() — функция вычисляет ранг каждой строки внутри партиции. Если есть повторяющиеся значения, функция возвращает одинаковый ранг для таких строчек, пропуская при этом следующий числовой ранг.
DENSE_RANK() — то же самое что и RANK, только в случае одинаковых значений DENSE_RANK не пропускает следующий числовой ранг, а идет последовательно.

Про NULL в случае ранжирования:
Для SQL пустые NULL значения будут определяться одинаковым рангом
Функции смещения:
Это функции, которые позволяют перемещаясь по выделенной партиции таблицы обращаться к предыдущему значению строки или крайним значениям строк в партиции.
LAG() — функция, возвращающая предыдущее значение столбца по порядку сортировки.
LEAD() — функция, возвращающая следующее значение столбца по порядку сортировки.
На простом примере видно, как можно в одной строке получить текущую оценку, предыдущую и следующую оценки Пети в четвертях.


FIRST_VALUE()/LAST_VALUE() — функции возвращающие первое или последнее значение столбца в указанной партиции. В качестве аргумента указывает столбец, значение которого нужно вернуть. В оконной функции под словом OVER обязательное указание ORDER BY условия.
В следующей версии статьи разберем отдельно такое понятие как фрейм окна функции или window frame и рассмотрим на простых примерах как он используется.