sqlite3 — DB-API 2.0 interface for SQLite databases
SQLite is a C library that provides a lightweight disk-based database that doesn’t require a separate server process and allows accessing the database using a nonstandard variant of the SQL query language. Some applications can use SQLite for internal data storage. It’s also possible to prototype an application using SQLite and then port the code to a larger database such as PostgreSQL or Oracle.
The sqlite3 module was written by Gerhard Häring. It provides an SQL interface compliant with the DB-API 2.0 specification described by PEP 249, and requires SQLite 3.7.15 or newer.
This document includes four main sections:
Tutorial teaches how to use the sqlite3 module.
Reference describes the classes and functions this module defines.
How-to guides details how to handle specific tasks.
Explanation provides in-depth background on transaction control.
The SQLite web page; the documentation describes the syntax and the available data types for the supported SQL dialect.
Tutorial, reference and examples for learning SQL syntax.
PEP 249 — Database API Specification 2.0
PEP written by Marc-André Lemburg.
Tutorial
In this tutorial, you will create a database of Monty Python movies using basic sqlite3 functionality. It assumes a fundamental understanding of database concepts, including cursors and transactions.
First, we need to create a new database and open a database connection to allow sqlite3 to work with it. Call sqlite3.connect() to create a connection to the database tutorial.db in the current working directory, implicitly creating it if it does not exist:
The returned Connection object con represents the connection to the on-disk database.
In order to execute SQL statements and fetch results from SQL queries, we will need to use a database cursor. Call con.cursor() to create the Cursor :
Now that we’ve got a database connection and a cursor, we can create a database table movie with columns for title, release year, and review score. For simplicity, we can just use column names in the table declaration – thanks to the flexible typing feature of SQLite, specifying the data types is optional. Execute the CREATE TABLE statement by calling cur.execute(. ) :
We can verify that the new table has been created by querying the sqlite_master table built-in to SQLite, which should now contain an entry for the movie table definition (see The Schema Table for details). Execute that query by calling cur.execute(. ) , assign the result to res , and call res.fetchone() to fetch the resulting row:
We can see that the table has been created, as the query returns a tuple containing the table’s name. If we query sqlite_master for a non-existent table spam , res.fetchone() will return None :
Now, add two rows of data supplied as SQL literals by executing an INSERT statement, once again by calling cur.execute(. ) :
The INSERT statement implicitly opens a transaction, which needs to be committed before changes are saved in the database (see Transaction control for details). Call con.commit() on the connection object to commit the transaction:
We can verify that the data was inserted correctly by executing a SELECT query. Use the now-familiar cur.execute(. ) to assign the result to res , and call res.fetchall() to return all resulting rows:
The result is a list of two tuple s, one per row, each containing that row’s score value.
Now, insert three more rows by calling cur.executemany(. ) :
Notice that ? placeholders are used to bind data to the query. Always use placeholders instead of string formatting to bind Python values to SQL statements, to avoid SQL injection attacks (see How to use placeholders to bind values in SQL queries for more details).
We can verify that the new rows were inserted by executing a SELECT query, this time iterating over the results of the query:
Each row is a two-item tuple of (year, title) , matching the columns selected in the query.
Finally, verify that the database has been written to disk by calling con.close() to close the existing connection, opening a new one, creating a new cursor, then querying the database:
You’ve now created an SQLite database using the sqlite3 module, inserted data and retrieved values from it in multiple ways.
How-to guides for further reading:
-
How to use placeholders to bind values in SQL queries
-
How to adapt custom Python types to SQLite values
-
How to convert SQLite values to custom Python types
-
How to use the connection context manager
-
How to create and use row factories
Explanation for in-depth background on transaction control.
Reference
Module functions
Open a connection to an SQLite database.
database ( path-like object ) – The path to the database file to be opened. Pass ":memory:" to open a connection to a database that is in RAM instead of on disk.
timeout (float) – How many seconds the connection should wait before raising an OperationalError when a table is locked. If another connection opens a transaction to modify a table, that table will be locked until the transaction is committed. Default five seconds.
detect_types (int) – Control whether and how data types not natively supported by SQLite are looked up to be converted to Python types, using the converters registered with register_converter() . Set it to any combination (using | , bitwise or) of PARSE_DECLTYPES and PARSE_COLNAMES to enable this. Column names takes precedence over declared types if both flags are set. Types cannot be detected for generated fields (for example max(data) ), even when the detect_types parameter is set; str will be returned instead. By default ( 0 ), type detection is disabled.
isolation_level (str | None) – The isolation_level of the connection, controlling whether and how transactions are implicitly opened. Can be "DEFERRED" (default), "EXCLUSIVE" or "IMMEDIATE" ; or None to disable opening transactions implicitly. See Transaction control for more.
check_same_thread (bool) – If True (default), ProgrammingError will be raised if the database connection is used by a thread other than the one that created it. If False , the connection may be accessed in multiple threads; write operations may need to be serialized by the user to avoid data corruption. See threadsafety for more information.
factory (Connection) – A custom subclass of Connection to create the connection with, if not the default Connection class.
cached_statements (int) – The number of statements that sqlite3 should internally cache for this connection, to avoid parsing overhead. By default, 128 statements.
Raises an auditing event sqlite3.connect with argument database .
Raises an auditing event sqlite3.connect/handle with argument connection_handle .
New in version 3.4: The uri parameter.
Changed in version 3.7: database can now also be a path-like object , not only a string.
New in version 3.10: The sqlite3.connect/handle auditing event.
Return True if the string statement appears to contain one or more complete SQL statements. No syntactic verification or parsing of any kind is performed, other than checking that there are no unclosed string literals and the statement is terminated by a semicolon.
This function may be useful during command-line input to determine if the entered text seems to form a complete SQL statement, or if additional input is needed before calling execute() .
sqlite3. enable_callback_tracebacks ( flag , / ) 
Enable or disable callback tracebacks. By default you will not get any tracebacks in user-defined functions, aggregates, converters, authorizer callbacks etc. If you want to debug them, you can call this function with flag set to True . Afterwards, you will get tracebacks from callbacks on sys.stderr . Use False to disable the feature again.
Register an unraisable hook handler for an improved debug experience:
Register an adapter callable to adapt the Python type type into an SQLite type. The adapter is called with a Python object of type type as its sole argument, and must return a value of a type that SQLite natively understands .
sqlite3. register_converter ( typename , converter , / ) 
Register the converter callable to convert SQLite objects of type typename into a Python object of a specific type. The converter is invoked for all SQLite values of type typename; it is passed a bytes object and should return an object of the desired Python type. Consult the parameter detect_types of connect() for information regarding how type detection works.
Note: typename and the name of the type in your query are matched case-insensitively.
Module constants
Pass this flag value to the detect_types parameter of connect() to look up a converter function by using the type name, parsed from the query column name, as the converter dictionary key. The type name must be wrapped in square brackets ( [] ).
This flag may be combined with PARSE_DECLTYPES using the | (bitwise or) operator.
Pass this flag value to the detect_types parameter of connect() to look up a converter function using the declared types for each column. The types are declared when the database table is created. sqlite3 will look up a converter function using the first word of the declared type as the converter dictionary key. For example:
This flag may be combined with PARSE_COLNAMES using the | (bitwise or) operator.
sqlite3. SQLITE_OK ¶ sqlite3. SQLITE_DENY ¶ sqlite3. SQLITE_IGNORE 
Flags that should be returned by the authorizer_callback callable passed to Connection.set_authorizer() , to indicate whether:
Access is allowed ( SQLITE_OK ),
The SQL statement should be aborted with an error ( SQLITE_DENY )
The column should be treated as a NULL value ( SQLITE_IGNORE )
String constant stating the supported DB-API level. Required by the DB-API. Hard-coded to "2.0" .
String constant stating the type of parameter marker formatting expected by the sqlite3 module. Required by the DB-API. Hard-coded to "qmark" .
The named DB-API parameter style is also supported.
Version number of the runtime SQLite library as a string .
Version number of the runtime SQLite library as a tuple of integers .
Integer constant required by the DB-API 2.0, stating the level of thread safety the sqlite3 module supports. This attribute is set based on the default threading mode the underlying SQLite library is compiled with. The SQLite threading modes are:
-
Single-thread: In this mode, all mutexes are disabled and SQLite is unsafe to use in more than a single thread at once.
-
Multi-thread: In this mode, SQLite can be safely used by multiple threads provided that no single database connection is used simultaneously in two or more threads.
-
Serialized: In serialized mode, SQLite can be safely used by multiple threads with no restriction.
The mappings from SQLite threading modes to DB-API 2.0 threadsafety levels are as follows:
Учебник по SQLite3 в Python

SQLite – это C библиотека, реализующая легковесную дисковую базу данных (БД), не требующую отдельного серверного процесса и позволяющую получить доступ к БД с использованием языка запросов SQL. Некоторые приложения могут использовать SQLite для внутреннего хранения данных. Также возможно создать прототип приложения с использованием SQLite, а затем перенести код в более многофункциональную БД, такую как PostgreSQL или Oracle.
Модуль sqlite3 реализует интерфейс SQL, соответствующий спецификации DB-API 2.0, описанной в PEP 249.
Создание соединения
Чтобы воспользоваться SQLite3 в Python необходимо импортировать модуль sqlite3, а затем создать объект подключения к БД.
Объект подключения создается с помощью метода connect() :
Курсор SQLite3
Для выполнения операторов SQL, нужен объект курсора, создаваемый методом cursor() .
Курсор SQLite3 – это метод объекта соединения. Для выполнения операторов SQLite3 сначала устанавливается соединение, а затем создается объект курсора с использованием объекта соединения следующим образом:
Теперь можно использовать объект курсора для вызова метода execute() для выполнения любых запросов SQL.
Создание базы данных
После создания соединения с SQLite, файл БД создается автоматически, при условии его отсутствия. Данный файл создаётся на диске, но также можно создать базу данных в оперативной памяти, используя параметр «:memory:» в методе connect . При этом база данных будет называется инмемори.
Рассмотрим приведенный ниже код, в котором создается БД с блоками try , except и finally для обработки любых исключений:
Сначала импортируется модуль sqlite3 , затем определяется функция с именем sql_connection . Внутри функции определен блок try , где метод connect() возвращает объект соединения после установления соединения.
Затем определен блок исключений, который в случае каких-либо исключений печатает сообщение об ошибке. Если ошибок нет, соединение будет установлено, тогда скрипт распечатает текст «Connection is established: Database is created in memory».
Далее производится закрытие соединения в блоке finally . Закрытие соединения необязательно, но это хорошая практика программирования, позволяющая освободить память от любых неиспользуемых ресурсов.
Создание таблицы
Чтобы создать таблицу в SQLite3, выполним запрос Create Table в методе execute() . Для этого выполним следующую последовательность шагов:
- Создание объекта подключения
- Объект Cursor создаётся с использованием объекта подключения
- Используя объект курсора, вызывается метод execute с SQL запросом create table в качестве параметра.
Давайте создадим таблицу Employees со следующими колонками:
Код будет таким:
В приведенном выше коде определено две функции: первая устанавливает соединение; а вторая — используя объект курсора выполняет SQL оператор create table .
Метод commit() сохраняет все сделанные изменения. В конце скрипта производится вызов обеих функций.
Для проверки существования таблицы воспользуемся браузером БД для sqlite.
Вставка данных в таблицу
Чтобы вставить данные в таблицу воспользуемся оператором INSERT INTO . Рассмотрим следующую строку кода:
Также можем передать значения / аргументы в оператор INSERT в методе execute () . Также можно использовать знак вопроса ( ? ) в качестве заполнителя для каждого значения. Синтаксис INSERT будет выглядеть следующим образом:
Где картеж entities содержат значения для заполнения одной строки в таблице:
Код выглядит следующим образом:
Обновление таблицы
Предположим, что нужно обновить имя сотрудника, чей идентификатор равен 2. Для обновления будем использовать инструкцию UPDATE . Также воспользуемся предикатом WHERE в качестве условия для выбора нужного сотрудника.
Рассмотрим следующий код:
Это изменит имя Andrew на Rogers.
Оператор SELECT
Оператор SELECT используется для выборки данных из одной или более таблиц. Если нужно выбрать все столбцы данных из таблицы, можете использовать звёздочку (*). SQL синтаксис для этого будет следующим:
В SQLite3 инструкция SELECT выполняется в методе execute объекта курсора. Например, выберем все стрики и столбцы таблицы employee :
Если нужно выбрать несколько столбцов из таблицы, укажем их, как показано ниже:
Оператор SELECT выбирает все данные из таблицы employees БД.
Выборка всех данных
Чтобы извлечь данные из БД выполним инструкцию SELECT , а затем воспользуемся методом fetchall() объекта курсора для сохранения значений в переменной. При этом переменная будет являться списком, где каждая строка из БД будет отдельным элементом списка. Далее будет выполняться перебор значений переменной и печатать значений.
Код будет таким:
Также можно использовать fetchall() в одну строку:
Если нужно извлечь конкретные данные из БД, воспользуйтесь предикатом WHERE . Например, выберем идентификаторы и имена тех сотрудников, чья зарплата превышает 800. Для этого заполним нашу таблицу большим количеством строк, а затем выполним запрос.
Можете использовать оператор INSERT для заполнения данных или ввести их вручную в программе браузера БД.
Теперь, выберем имена и идентификаторы тех сотрудников, у кого зарплата больше 800:
В приведенном выше операторе SELECT вместо звездочки (*) были указаны атрибуты id и name.
SQLite3 rowcount
Счётчик строк SQLite3 используется для возврата количества строк, которые были затронуты или выбраны последним выполненным запросом SQL.
Когда вызывается rowcount с оператором SELECT , будет возвращено -1, поскольку количество выбранных строк неизвестно до тех пор, пока все они не будут выбраны. Рассмотрим пример:
Поэтому, чтобы получить количество строк, нужно получить все данные, а затем получить длину результата:
Когда оператор DELETE используется без каких-либо условий (предложение where ), все строки в таблице будут удалены, а общее количество удаленных строк будет возвращено rowcount .
Если ни одна строка не удалена, будет возвращено 0.
Список таблиц
Чтобы вывести список всех таблиц в базе данных SQLite3, нужно обратиться к таблице sqlite_master , а затем использовать fetchall() для получения результатов из оператора SELECT .
Sqlite_master — это главная таблица в SQLite3, в которой хранятся все таблицы.
Проверка существования таблицы
При создании таблицы необходимо убедиться, что таблица еще не существует. Аналогично, при удалении таблицы она должна существовать.
Чтобы проверить, если таблица еще не существует, используем «if not exists» с оператором CREATE TABLE следующим образом:
Точно так же, чтобы проверить, существует ли таблица при удалении, мы используем «if not exists» с инструкцией DROP TABLE следующим образом:
Также проверим, существует ли таблица, к которой нужно получить доступ, выполнив следующий запрос:
Если указанное имя таблицы не существует, будет возвращен пустой массив.
Удаление таблицы
Удаление таблицы выполняется с помощью оператора DROP . Синтаксис оператора DROP выглядит следующим образом:
Чтобы удалить таблицу, таблица должна существовать в БД. Поэтому рекомендуется использовать «if exists» с оператором DROP . Например, удалим таблицу employees :
Исключения SQLite3
Исключением являются ошибки времени выполнения скрипта. При программировании на Python все исключения являются экземплярами класса производного от BaseException .
В SQLite3 у есть следующие основные исключения Python:
DatabaseError
Любая ошибка, связанная с базой данных, вызывает ошибку DatabaseError .
IntegrityError
IntegrityError является подклассом DatabaseError и возникает, когда возникает проблема целостности данных, например, когда внешние данные не обновляются во всех таблицах, что приводит к несогласованности данных.
ProgrammingError
Исключение ProgrammingError возникает, когда есть синтаксические ошибки или таблица не найдена или функция вызывается с неправильным количеством параметров / аргументов.
OperationalError
Это исключение возникает при сбое операций базы данных, например, при необычном отключении. Не по вине программиста.
NotSupportedError
При использовании некоторых методов, которые не определены или не поддерживаются базой данных, возникает исключение NotSupportedError .
Массовая вставка строк в Sqlite
Для вставки нескольких строк одновременно использовать оператор executemany .
Рассмотрим следующий код:
Здесь создали таблицу с двумя столбцами, тогда у «данных» есть четыре значения для каждого столбца. Эта переменная передается методу executemany() вместе с запросом.
Обратите внимание, что использовался заполнитель для передачи значений.
Закрытие соединения
Когда работа с БД завершена, рекомендуется закрыть соединение. Соединение может быть закрыто с помощью метода close() .
Чтобы закрыть соединение, используйте объект соединения с вызовом метода close() следующим образом:
SQLite3 datetime
В базе данных Python SQLite3 можно легко сохранять дату или время, импортируя Python модуль datetime. Следующие форматы являются наиболее часто используемыми форматами для даты и времени:
Рассмотрим следующий код:
В этом коде модуль datetime импортируется первым, далее создали таблицу с именем assignments с тремя столбцами.
Тип данных третьего столбца — дата. Чтобы вставить дату в столбец, воспользовались datetime.date . Точно так же можно использовать datetime.time для обработки времени.
Вывод
SQLite можно использовать в своих разработках, но с учетом особенностей этой БД. SQLite прекрасно подойдет для проектов у которых мало операций записи, не нужна система прав доступа к БД и ограниченны ресурсы сервера.
Python Select from SQLite Table
This lesson demonstrates how to execute SQLite SELECT Query from Python to retrieve rows from the SQLite table using the built-in module sqlite3.
Goals of this lesson
- Fetch all rows using a cursor.fetchall()
- Use cursor.fetchmany(size) to fetch limited rows, and fetch only a single row using cursor.fetchone()
- Use the Python variables in the SQLite Select query to pass dynamic values.
Also Read:
- Solve Python SQLite Exercise
- Read Python SQLite Tutorial (Complete Guide)
Table of contents
Prerequisite
Before executing the following program, please make sure you know the SQLite table name and its column details.
For this lesson, I am using the ‘SqliteDb_developers’ table present in my SQLite database.
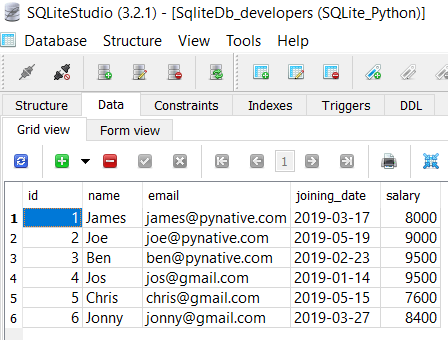
sqlitedb_developers table with data
If a table is not present in your SQLite database, then please refer to the following articles: –
Steps to select rows from SQLite table
How to Select from a SQLite table using Python
-
Connect to SQLite from Python
Refer to Python SQLite database connection to connect to SQLite database.
Next, prepare a SQLite SELECT query to fetch rows from a table. You can select all or limited rows based on your requirement.
For example, SELECT column1, column2, columnN FROM table_name;
Next, use a connection.cursor() method to create a cursor object. This method returns a cursor object. The Cursor object is required to execute the query.
Execute the select query using the cursor.execute(query) method.
After successfully executing a select operation, Use the fetchall() method of a cursor object to get all rows from a query result. it returns a list of rows.
Iterate a row list using a for loop and access each row individually (Access each row’s column data using a column name or index number.)
use cursor.clsoe() and connection.clsoe() method to close the SQLite connection after your work completes.
Example to read all rows from SQLite table
Output:
Note: I am directly displaying each row and its column values. If you want to use column values in your program, you can copy them into python variables to use it. For example, name = row[1]
Use Python variables as parameters in SQLite Select Query
We often need to pass a variable to SQLite select query in where clause to check some condition.
Let’s say the application wants to fetch person details by giving any id at runtime. To handle such a requirement, we need to use a parameterized query.
A parameterized query is a query in which placeholders ( ? ) are used for parameters and the parameter values supplied at execution time.
Example
Select limited rows from SQLite table using cursor.fetchmany()
In some circumstances, fetching all the data rows from a table is a time-consuming task if a table contains thousands of rows.
To fetch all rows, we have to use more resources, so we need more space and processing time. To enhance performance, use the fetchmany(SIZE) method of a cursor class to fetch fewer rows.
Note: In the above program, the specified size is 2 to fetch two records. If the SQLite table contains rows lesser than the specified size, then fewer rows will return.
Select a single row from SQLite table
When you want to read only one row from the SQLite table, then you should use fetchone() method of a cursor class. You can also use this method in situations when you know the query is going to return only one row.
The cursor.fetchone() method retrieves the next row from the result set.
Next Steps:
To practice what you learned in this article, Please solve a Python Database Exercise project to Practice and master the Python Database operations.
Did you find this page helpful? Let others know about it. Sharing helps me continue to create free Python resources.
About Vishal
Founder of PYnative.com I am a Python developer and I love to write articles to help developers. Follow me on Twitter. All the best for your future Python endeavors!
Related Tutorial Topics:
Python Exercises and Quizzes
Free coding exercises and quizzes cover Python basics, data structure, data analytics, and more.
The Novice’s Guide to the Python 3 DB-API
The source for this guide lives in GitHub here.
Overview
The standard API for interacting with relational databases in Python is defined in PEP 249 Python Database API Specification v2.0.
The most popular database libraries are:
- SQLite: sqlite3
- Pyscopg: psycopg2
- MySQL: mysql
- Oracle: cx_Oracle
- MS SQL Server: pypyodbc, pyodbc, pymssql
Importing
There are three common ways of importing the DB-API implementation library
In general, the only function used directly in the library is connect , as most other operations are performed on objects returned after calling this.
Connecting
The two top-level objects when working with the DB-API are the connection and the cursor. First you get a connection to a database:
There are several ways to specify the database connection parameters. For most libraries, the default values for the connect method will connect to a default configured locally-installed database. Some databases have their own options, like sqlite3 has the option for a non-persistent, in-memory database:
Next you get a cursor, which will be used for executing transactional commands, SQL queries, and data manipulations.
The best way to use the connection and cursor are from within resource handlers. Most database libraries support resource handling on the connection, but only a few support it on the cursor. Using with , both the connection and cursor are closed after usage.
If only connection resource handling is supported, then the cursor must be wrapped in a try/finally block to ensure the cursor is closed:
If connection resource handling is not supported, both have close() methods which must be called as part of a finally block:
All libraries for databases that support transactions will automatically start a new one when the first statement on a new cursor or immediatly after a call to commit() on a cursor. All cursors on the connection will execute within that transaction. If using with for resource handling, the transaction will be committed at the end of the block. If manually managing the resources, this transaction must be explicitly committed before closing the connection, or it will be automatically rolled back. Rollback and commit are done with the methods of the same name:
Autocommit can also be enabled by setting conn.autocommit = True in pyscopg2 after creating the connection but before the first execute.
Exception handling can be done either with the generic Exception class or with classes specific to each library.
Query
A cursor has only two methods, execute and executemany , which are used for all queries and DML:
For queries which involve parameters, there are five styles of substitution built into the execute methods:
- qmark ‘INSERT INTO actors(first_name, last_name, birth_date) VALUES (?, ?, ?)’
- numeric INSERT INTO actors(first_name, last_name, birth_date) VALUES (:1, :2, :3)’
- named ‘INSERT INTO actors(first_name, last_name, birth_date) VALUES (:first_name, :last_name, :birth_date)’
- format ‘INSERT INTO actors(first_name, last_name, birth_date) VALUES (%s, %s, %s)’
- pyformat ‘INSERT INTO actors(first_name, last_name, birth_date) VALUES (%(first_name)s, %(last_name)s, %(birth_date)s)’
It is highly encouraged to use one of these forms of substitution rather than doing direct string construction or replacement. Using Python’s built-in formatting operators is not the correct way to do this.
Each DB-API is only required to support one of these, but most libraries support more than one.
- sqlite3: qmark, numeric, and named
- pyscopg: format, pyformat
- PyMySQL: format
- cx_Oracle: named
If you want to tell at least one of the styles your DB-API library supports, each library has a global variable paramstyle that has the value, e.g., sqlite3.paramstyle
Use placeholders in the statement, and then pass a tuple for positional parameters or a dictionary for named parameters.