SQL Server Statistics: Problems and Solutions
SQL Server Statistics assist the query optimiser to calculate the best way of running the query. Holger describes every common way that things can go wrong with statistics, and how to put matters right.
Normally, you do not need to be too concerned about the way that your SQL Queries are executed. These are passed to the Query Optimizer which first checks to see if it has a plan already available to execute it. If not, it compiles a plan. To do so effectively, it needs to be able to estimate the intermediate row counts that would be generated from the various alternative strategies for returning a result. The Database Engine keeps statistics about the distribution of the key values in each index of the table, and uses these statistics to determine which index or indexes to use in compiling the query plan. If, however, there are problems with these statistics then the performance of queries will suffer. So what could go wrong, and what can be done to put things right? We’ll go through the most common problems and explain how it might happen and what to do about it.
Contents
There is no statistics object at all
AUTO CREATE STATISTICS is OFF
Table variables
XML and spatial data
Remote queries
The database is read only
Perfect statistics exist, but can’t be used properly
Utilization of local variables in TSQL scripts
Providing expressions in predicates
Parameterization issues
Statistics is too imprecise
Insufficient sample size
Statistics’ granularity is too broad
Stale statistics
No automatic generation of multi-column statistics
Statistics for correlated columns are not supported
Updates of statistics come at a cost
Memory allocation problems
An Overestimate of memory requirements
An Underestimate of memory requirements
Best practices
There is no statistics object at all
If there’s no statistics, the optimizer will have to guess row-counts rather than estimate them, and believe me: this is not what you want!
There are several ways of finding out from both the estimated and actual execution plans whether the optimizer comes across missing statistics. In this case you’ll see warnings in the plan. The there will be an exclamation mark in the graphical execution plan and a warning in the extended operator information, just like the one in Picture 1. You won’t see this warning for table variables, so watch out for table scans on table variables and their row-count estimations.
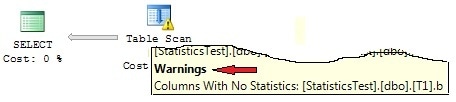
Picture 1: Missing statistics warning
If you want to have a look at execution plans for preceding queries, you may request these plans by the use of the sys.dm_exec_cached_plans DMV.
SQL Server Profiler offers another option. If you include the event Errors and Warnings/Missing Column Statistics in your profile, you’ll observe a log entry whenever the optimizer detects a missing statistics. Be aware however that this event will not be fired if AUTO CREATE STATISTICS is enabled for the database or table.
There are several circumstances under which you’ll experience missing statistics.
AUTO CREATE STATISTICS is OFF
If you’ve set the option AUTO CREATE STATISTICS OFF and overlooked the task of creating statistics manually, the optimizer will suffer from missing statistics.
Rely instead on the automatic creation of statistics by setting AUTO CREATE STATISTICS to ON.
Table variables
For table variables, statistics will never be maintained. Keep that in mind: no statistics for table variables! When selecting from table variables, the estimated row-count is always 1, unless a predicate that evaluates to false, and doesn’t have any relationship to the table variable, is applied (such as WHERE 1=0), in which case the estimated row-count evaluates to 0.
Don’t count on using table variables for temp tables if they are likely to contain more than a few rows. As a rule of thumb, use temporary tables (tables with a “#” as their name’s first character), rather than table variables, for temp tables with more than 100 rows.
XML and spatial data
SQL Server does not maintain statistics for XML and spatial data types. That’s just a fact, not a problem. So, don’t try to find statistics for these columns, as they’re simply not there.
If you experience performance problems with queries that have to search through XML data, or filter spatial columns e.g., XML or spatial indexes may help. But that’s another story and beyond the scope of this article.
Remote queries
Suppose that you query a table from an Oracle database via a linked server connection and join this table to some local database tables. It’s perfectly understandable that SQL Server has no idea of any row-counts from that remote table, since it is residing in an Oracle database. This can occur, if you use OPENROWSET or OPENQUERY for remote data access.
But you may also face this issue out of the blue, when working with DMVs. A certain number of SQL Server’s DMVs are no more than a shell for querying data from internal tables. You may see a Remote Scan operator for SQL Server 2005 or a Table Valued Function operator for SQL Server 2008 in this case. Those operators have tied default cardinality estimations. (Depending on the server version and the operator, these are 1, 1000, or 10000.)
Have a look at the following query:
Here’s what BOL states:
“Returns a single row that displays the state information of the transaction in the current session.”
But look at the execution plan in Picture 2. No estimated row-count of 1 there. Apparently the optimizer does not take BOL content into account when generating the plan. You see the internal table DM_TRAN_CURRENT_TRANSACTION that is called by invoking OPENROWSET and an estimated row-count of 1000, which is far from reality.
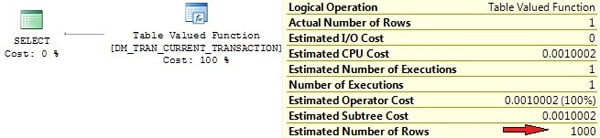
Picture 2: Row-count estimation for TVF
If possible, give the optimizer some support by specifying the row-count through the TOP(n) clause. This will only be effective if n is less than the Estimated Number of Rows, 1000 in our example. So, if you have a guess of how many rows your Oracle query is about to return, just add TOP(n) to your OPENQUERY statement. This will help for better cardinality estimations and be useful if you utilize the OPENROWSET result for further joining or filtering. But be sure that this practice is somewhat dangerous. If you specify a value too low for n, your result set will lose rows, which would be a disaster.
With our example using sys.dm_tran_current_transaction , you would do better by rewriting the query like this:
Normally this won’t be necessary, because the simple SELECT, if used stand-alone, is quick enough. However, if you process the query result further by, perhaps, using it in joins, then the TOP 1 is useful.
If you find that you are using the OPENQUERY results in more complex queries for joining or filtering operations, then it is wise to import the OPENQUERY result into a local table first. Statistics and indexes can be properly maintained for this local table, so the optimizer then has enough information for realistic estimations of row-counts.
The database is read only
If your database is set to read-only, the optimizer can’t add missing statistics even with AUTO CREATE STATISTICS enabled, because changes to read only databases are generally prevented.
Watch out for the fact that there is also a special kind of read only database. Yes, I’m talking about a snapshot! If the optimizer is missing the statistics for database snapshots, these can’t be created automatically. This is likely to happen if snapshots are being used for reporting applications. I often read suggestions to create snapshots for reporting purposes so as to avoid running those long running and resource-intensive reporting queries on the underlying OLPT systems. That may be fine up to a point, but Reporting queries are highly unpredictable and usually differ from normal OLTP queries. Therefore, there’s a chance that your reporting queries will suffer from missing statistics or, even worse, missing indexes.
If you set your database to read-only, you’ll have to create your statistics manually before you do so.
Perfect statistics exist, but can’t be used properly
There is always a possibility that the optimizer cannot use statistics even if they are in place and up-to-date. This can be caused by poor TSQL code such as you’ll see in this section.
Utilization of local variables in TSQL scripts
Let’s again have a look at this query form our introductory example:
Picture 5 of the first part shows the actual execution plan, which reveals a large discrepancy between the actual and estimated row-count. But what’s the reason for this difference?
If you’re familiar with the different steps of query execution, you’ll realize the answer to this. Before a query is executed, a query plan has to be generated, and right at the time of the compilation of the query, SQL Server does not know the value of variable @x. Yes of course, in our case it’d be easy to determine the value of @x, but there may be more complicated expressions that prevent the calculation of @x’s value at compile time In this case, the optimizer has no knowledge of the actual value of @x and is therefore unable to do a reasonable estimation of cardinality from the histogram.
But wait! At least there’s a statistics for column c1, so if the optimizer can’t browse the histogram, it may probably fall back to other, more general quantities. That’s exactly what happens here.
In case the optimizer can’t take advantage of a statistic’s histogram, the estimations of cardinality are determined by examining the average density, the total number of rows in the table, and possibly also the predicate’s operator(s). If you look at the example from the first part, you’ll see that we inserted 100001 rows into our test table, where column c1 had a value of 2000 for only one row and a value of 1000 for the remaining 100000 rows. You can inspect the average density of the statistics by executing DBCC SHOW_STATISTICS, but remember that this value calculates to 1/distinct number of values, which evaluates to 1/2=0.5 in our case. Hence, the optimizer calculates the average number of rows per distinct value of c1 to 100001 rows * 0.5 = 50000.5 rows. With this value at hand, the predicate’s operator comes into play, which is “=” in our example. For the exact comparison, the optimizer assumes that the average number of rows for one value of c1 will be returned, thus the expected row-count is 50000.5 (again, see Picture 5 of part one).
Other comparison operators lead to different estimates of selectivity, where the average density may or may not be considered. If ‘greater’ or ‘less than’ operators are applied, then it’s just assumed that 30% of all table rows will be returned. You can easily verify this by playing around with our little test script.
If possible, avoid the using local variables in TSQL scripts. As this may not always be practicable, there are also other options available.
First, you may consider introducing stored procedures. These are perfectly designed for working with parameters by using a technique that’s called parameter sniffing. When a procedure is called for the first time, the optimizer will figure out any provided parameters and adjust the generated plan (and cardinality estimations, of course) according to these parameters. Although you might face other problems with this approach (see below), it is a perfect solution in our case.
If we embed our query into a stored procedure like this:
And then just execute this procedure by invoking:
The execution plan will expose an Index Seek, and thus look as it should. That’s because the optimizer knows it has to generate the plan for a value of @x=2000.
Picture 3 reveals the plan. Compare this to the original plan presented in Picture 5 of part one.
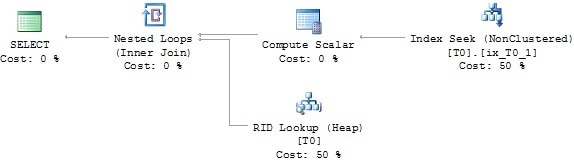
Picture 3: Execution plan of stored procedure
Secondly, you may consider solving the issue by the use of dynamic SQL. Ok, just to clarify this: No, no, no, I do not suggest using dynamic SQL in general and extensively. By no means would that be appropriate! Dynamic SQL has very bad side effects, such as possible Plan cache pollution, vulnerability to SQL injection attacks, and possibly increased CPU- and memory utilization. But look at this:
The execution plan is flawless now (same as in Picture 3), since it is created during the execution of the EXEC command, and the provided command string is passed as parameter to this command. In reality, you’d have to balance the consequences before deciding to use dynamic SQL. But you can see that, if carefully chosen and selectively applied, dynamic SQL is not bad in all cases. Altogether it’s very simple: just be aware of what you do!
More often than not the extended stored procedure sp_executesql will help you using dynamic SQL, while also excluding some of the dynamic SQL drawbacks at the same time.
Here’s our example again, this time re-written for sp_executesql:
Once more the execution plan looks like the one presented in Picture 3.
Providing expressions in predicates
Using expressions in predicates may also prevent the optimizer from using the histogram. Look at the following example:
The execution plan is shown in Picture 4.
Picture 4: Bad cardinality estimation because of expression in predicate
So, although a statistics for columns c1 exists, the optimizer has no idea of how to apply this statistics to the expression POWER(c1,1) and therefore has to guess the row-count here. This is very similar to the problem of the missing statistics we’ve mentioned already, because there’s simply no statistics for the expression POWER(c1,1). In terms of the optimizer, POWER(c1,1) is called a non-foldable expression. Please refer to this article for more information.
If possible, re-write your SQL Code so that comparisons are only done with “pure” columns. So e.g. instead of specifying
You would do better to write:
Fortunately the optimizer is quite smart when evaluating expressions and in some cases will do the re-write internally (again see here for some more information about this).
If re-writing your query is not possible, I suggest you ask a colleague for assistance. If it’s still not feasible, you may take calculated columns into account. Calculated columns will work out fine, since statistics are also maintained for calculated columns. Furthermore you may also create indexes for calculated columns, which you can’t do for expressions.
Parameterization issues
If you use parameterized queries, such as the stored procedure in a previous example, you might face another problem. You’ll remember that the query plan is actually generated on the first call of the procedure, not the CREATE PROCEDURE statement. That’s the way, parameter sniffing works. The plan will be generated by utilizing row-count estimations for the provided parameter values that were provided at the first call. The problem here is quite obvious. What, if the first call is done with uncharacteristic parameter values? Cardinality estimations will use these values and the created execution plan then goes into the plan cache. The plan will have a poor estimation of row-counts, so subsequent reuse of the plan with more usual parameter values are likely to suffer poor performance.
Have a look at our stored procedure call:
If this is the first call of the procedure, the plan is generated for the filter WHERE c1=2000. Since there’s only one estimated row for c1=2000, an Index Seek is performed. If we’d call the procedure a second time like this:
The cached plan is re-used and again an Index Seek is performed. This is a very bad choice, because the query will now return 100000 rows. There is a big difference between the estimated and actual row-count! A Table Scan had been much more efficient here.
There’s another issue with parameterization that is very similar to the problem of using local variables in TSQL scripts that we’ve already written about. Consider this stored procedure:
Modifying the value of @x is not ideal. The parameter sniffing technique will not trace any modifications of @x, so the execution plan is adjusted to the provided value of @x only, not the actual value that is used inside the query. If you call the above stored procedure like this:
Then, the plan actually gets optimized for the filter WHERE c1=1000 and not WHERE c1=2000!
You really fool the optimizer by this practice, and unsatisfactory estimations of cardinality are highly likely to happen.
If you are having problems that are caused by parameter sniffing, you can consider using query plan hints, such as OPTIMIZE FOR, or WITH RECOMPILE. This topic is outside the scope of this article, however.
Try not to modify parameter values within stored procedures. Doing so will outfox parameter sniffing. If you have to change parameter values for further processing, you might consider splitting the stored procedure into several smaller stored procedures. Introduce stored procedures in the sense of sub-routines. Modify any parameter values in the frame procedure and call your sub-routine procedure by using the changed value. As for every stored procedure, a separate plan is generated: This practice will circumvent the issue.
Statistics is too imprecise
Generally we have to accept a certain amount of uncertainty with distribution statistics. After all, statistics perform some data reduction, and information losses are inevitable. But if the information that we lose is crucial for the optimizer to make a proper estimate of cardinality, we must look for some other solution. How can statistics objects become just too imprecise to be useful?
Insufficient sample size
Imagine a table with some million rows. Whenever SQL Server automatically creates or updates statistics for one of the columns of this table, it won’t take all of the table’s rows into account. To prevent exhaustive use of resources, like CPU and IO, usually only some sample rows are processed for the maintenance of statistics. This could lead to a histogram that poorly represents the overall distribution of data. If the optimizer estimates the cardinality, it may not be able to find enough information to generate an efficient query plan.
The general solution is very simple. You’ll have to interfere in the automatic update or creation of statistics by manual updates or generation of statistics. Remember that you can specify the sample size or even perform a full scan when invoking CREATE STATISTICS or UPDATE STATISTICS.
Remember that an index rebuild will always force the production of statistics that are created with a full scan. Be aware though that an index rebuild has no effect on column statistics but only regards index-related statistics.
Statistics’ granularity is too broad
Let’s come back to our table with multi-million rows again. Although the maximum size of the histogram is always limited to 200 entries, we know that we only have 200 clues for row-count estimations of a, let’s say a 4 million rows table. That’s an average of 4000000 rows/200 steps = 20000 rows per histogram step. If the column’s values were equally shared across all rows this won’t be a problem, but what if they aren’t? The statistics will probably be too coarse-grained and lead to inaccurate estimations of cardinality.
Apparently it would be helpful to increase the histogram size, but we can’t do that can we? No, there’s no way of enlarging the size of a histogram to contain more than 200 entries. But if we can’t include more rows into one histogram, how about simply using more than one histogram? Of course we can achieve that by introducing filtered statistics. Since the histogram is always tied to a single statistics, we can have multiple histograms for the same column when using filtered statistics.
You will have to create these filtered statistics manually, and you’ll have to be aware of the consequences that I’ll explain a bit later.
Let’s just return to a previous example and imagine that we have a table containing 90% of historical data (that never get changed) and only 10% of active data. Gladly we decide on having two filtered statistics, and separate these two statistics objects by applying a filter condition to some date column. (You might prefer two filtered indexes but, for this illustration, it doesn’t matter whether it’s filtered indexes or statistics.) Additionally, we can disable automatic updates for the statistics that represent only historical data (the 90% part): This is because it is only our active part, the 10%-part, for which the statistics need to be regularly refreshed.
At this point we hit a problem: With CREATE AUTO STATISTICS set to ON, the optimizer will always add an unfiltered statistics object as well, even if filtered statistics for the same column already exist. This automatically-added statistics will also have the ‘automatic update’ option enabled. Therefore, although it may seem that the two filtered statistics are the only ones in place, one for the historical, and another one for the active part, you’ll end up with a total of three statistics, since another (unfiltered) one has been automatically added. Not only do we now have the superfluous unfiltered statistics but there will also be pointless automatic updates to it. Of course we could disable the automatic creation of statistics for the entire table, but this would put the onus on us for creating all appropriate statistics. I don’t like this idea very much. If there’s an automatic option, why not rely on it whenever possible.
I think the best way to overcome this issue is to create the unfiltered statistics manually by specifying the NORECOMPUTE option. This will prevent the optimizer from adding this statistics object and will also avoid further automatic updates.
The steps necessary are as follows:
- Create one unfiltered statistics with NORECOMPUTE set to ON in order to prevent automatic updates. This statistics is only needed to “mislead” the optimizer.
- Create another filtered statistics for the 10% active part, but this time with automatic updates enabled.
- If desirable, create another filtered statistics for the 90% part and again, disable automatic updates.
If you follow the above steps, you will obtain more decent statistics for the active part of your table. But unfortunately this solution is not free of hitches, as the next section will reveal.
Stale statistics
I’ve already mentioned that the synchronization of statistics always lags behind actual data modifications. Therefore, almost every statistics object is stale – at least to a certain level. In many cases this behavior is absolutely acceptable, but there are also situations where the deviation between source data and statistics may be too great.
You already know that for tables with more than 500 rows at least 20% of a column’s data had to be changed in order to invalidate any linked statistics, so that these statistics receive an update next time they’re needed. That threshold of “at least 20%” can be far too large under several circumstances. This is best explained by introducing another sample.
CREATE INDEX and STATISTICS_NORECOMPUTE
Question : When a CREATE INDEX is executed on an existing table with rows in it, is it required to execute a UPDATE STATISTICS or will CREATE INDEX update the stats? Does the STATISTICS_NORECOMPUTE effect whether statistics are updated on a INDEX rebuild?
Answer : The STATISTICS_NORECOMPUTE setting doesn’t determine whether statistics re refreshed by this index rebuild. An index rebuild refreshes index statistics. It can’t be disabled.
Stabilizing Execution Plans: Plan Guides and NORECOMPUTE
 What could go wrong?
Sometimes you end up in a good plan / bad plan situation: an important query runs just fine most of the time. The query is parameterized, a good execution plan gets re-used, everything is cool.
But sometimes, a “bad plan” gets compiled and starts to be reused. This is “bad” parameter sniffing. “Bad plans” can come in a few varieties: maybe it’s slow some parameter combinations and can cause page timeouts sometimes. Maybe the “bad” query plan has a very large workspace memory grant that just isn’t needed, and it causes problems because lots of different queries are using it — then you get all sorts of nasty Resource Semaphore waits and everything gets slow.
Whatever the situation is, sometimes you want to stabilize a particular execution plan that’s “good” for all the different parameters that the query can run with.
Option 1: Change the code
The very best option is changing the code so you don’t have to resort to shenanigans behind the scenes. You can rewrite the TSQL, change indexes, or use hints to get a specific plan. But sometimes this is difficult to do: maybe it’s vendor code you can’t change. Maybe there’s a long code release process and it will take a very long time to get the code changed.
If you can tune the code, absolutely do it. If you can’t, at least get the request to fix the code noted by the vendor or software development team. Don’t skip it altogether, because the options I describe below aren’t all that fantastic.
Option 2: Plan guide that thing
Plan guides are like duct tape: it’s something you want to have on hand for emergency quick fixes, but you don’t want to rely on it long term as a building material. It’s also not suited for every kind of fix.
Plan guides let you do a few things:
- Apply query hints like “optmize for value”, “optimize for unknown”, “recompile”, and “maxdop” to a query
- Selectively turn on trace flags for a query, such as TF 4199 (performance optimizer changes), TF 9481(Older cost-based optimizer if running on SQL Server 2014), TF 2312 (newer cost-based optimizer if running on SQL Server 2014)
- Add selected table hints, like forceseek and specific index hints. (You cannot add NOLOCK or change isolation levels, don’t get too excited.)
- “Template” plan guides let you “force parameterize” a specific query, or enforce “simple parameterization” for a certain query if the database is using forced parameterization
But duct tape isn’t perfect. Here’s the biggest gotchas that I’ve found with plan guides:
- I’ve found that trying to use an index hint in a plan guide can cause queries to silently fail. That’s awkward.
- Plan guides don’t work with all types of queries. I haven’t been able to get them to work with temporary tables or table variables referenced in the query, for example.
- Making sure that a plan guide is working and is picking up your query is tricky. Plan guides are very picky about matching query text exactly.
- Plan guides can make code releases fail. If you’ve got a plan guide that references a stored procedure and something goes to alter it, SQL Server’s going to stop the ALTER with an error.
My biggest advice for plan guides: test them out on a non production system first. Verify that the plan guide is working and that the queries are doing exactly what you want before deploying to production. Treat the plan guide like real code as much as possible: put it into all environments, check it into source, use change control, and document it.
Option 3: Manually Force the “Right” Parameter Sniffing
If you can’t change the code and a plan guide doesn’t work, you can get a little creative. (By “get a little creative”, I mean that everything I’m about to describe can go horribly wrong.)
First, find the bad plan in cache. In SQL Server 2008 and higher, we get a nifty plan_hash for query plans. You can identify the “bad plan hash” that you don’t want to keep in cache. When it’s in cache, you then:
- Remove it from the cache. You can do this using DBCC FREEPROCCACHE and the plan_handle value (you can get this by running: sp_BlitzCache @results=’expert’). Or if it’s a stored procedure, you can use the sp_recompile procedure against the stored procedure to blow away the plan. (Thanks @DBArgenis for this tip!)
- Run a version of the query that puts the plan you want to be in cache. Usually this means running a version of the query with the parameters that give you the “right” plan.
You’ve got the burden of doing a some testing. Be careful with how you remove plans from cache: sp_recompile requires a schema level (exclusive) lock, so I don’t recommend running that against tables.
You need to generate the plan in a way that’s going to be re-used and make sure it works. You need to make sure that the plan you’re putting in cache really is good for re-use!
Stabilizing execution plans with NORECOMPUTE
 NORECOMPUTE – flimsy tape
If this doesn’t sound quite crazy enough for you, you can go a little farther and try to increase the chances of your “good” plan staying in cache longer. One tool you can use for this is NORECOMPUTE.
When you update statistics on a table with NORECOMPUTE, you tell SQL Server not to automatically update statistics on the table as data changes. This will automatically happen when approximately 20% of the rows in the table have been modified (the algorithm is more complicated, but 20% is pretty easy to remember). Updated statistics will cause the optimizer to consider a new execution plan for your query. So NORECOMPUTE reduces the chance of the “good” query being bumped out.
If you use NORECOMPUTE, be aware that this could have a negative effect on some queries and cause them to get a terrible estimate on queries that they’re running. You probably want to manually update statistics for the table at least once a day if data changes in it. You can do this using a built in command like sp_updatestats, custom code you write yourself, or Ola Hallengren’s free index maintenance scripts (see Examples B & D for two options). Just please don’t do it with a maintenance plan.
Document the heck out of this. It’s easy for people to have no idea it’s in place, or find it and change it without knowing what it impacts. If plan guides are duct tape, this is more like Scotch Tape.
These Are Emergency Fixes – Don’t Start Your Performance Tuning Process With These Techniques
A lot of times you don’t need any of this crazy stuff. Remember: many times you can fix these issues with good indexing or simple code changes. Safety first!
Learn More in Our Training
Our training class explains how to get an execution plan, how to read the operators, and learn solutions to common query problems.
UPDATE STATISTICS (Transact-SQL)
Updates query optimization statistics on a table or indexed view. By default, the query optimizer already updates statistics as necessary to improve the query plan; in some cases you can improve query performance by using UPDATE STATISTICS or the stored procedure sp_updatestats to update statistics more frequently than the default updates.
Updating statistics ensures that queries compile with up-to-date statistics. However, updating statistics causes queries to recompile. We recommend not updating statistics too frequently because there is a performance tradeoff between improving query plans and the time it takes to recompile queries. The specific tradeoffs depend on your application. UPDATE STATISTICS can use tempdb to sort the sample of rows for building statistics.
Syntax
Arguments
table_or_indexed_view_name
Is the name of the table or indexed view that contains the statistics object.
index_or_statistics_name
Is the name of the index to update statistics on or name of the statistics to update. If index_or_statistics_name is not specified, the query optimizer updates all statistics for the table or indexed view. This includes statistics created using the CREATE STATISTICS statement, single-column statistics created when AUTO_CREATE_STATISTICS is on, and statistics created for indexes.
For more information about AUTO_CREATE_STATISTICS, see ALTER DATABASE SET Options (Transact-SQL). To view all indexes for a table or view, you can use sp_helpindex.
FULLSCAN
Compute statistics by scanning all rows in the table or indexed view. FULLSCAN and SAMPLE 100 PERCENT have the same results. FULLSCAN cannot be used with the SAMPLE option.
SAMPLE number < PERCENT | ROWS >
Specifies the approximate percentage or number of rows in the table or indexed view for the query optimizer to use when it updates statistics. For PERCENT, number can be from 0 through 100 and for ROWS, number can be from 0 to the total number of rows. The actual percentage or number of rows the query optimizer samples might not match the percentage or number specified. For example, the query optimizer scans all rows on a data page.
SAMPLE is useful for special cases in which the query plan, based on default sampling, is not optimal. In most situations, it is not necessary to specify SAMPLE because the query optimizer uses sampling and determines the statistically significant sample size by default, as required to create high-quality query plans.
Starting with SQL Server 2016 (13.x) sampling of data to build statistics is done in parallel, when using compatibility level 130, to improve the performance of statistics collection. The query optimizer will use parallel sample statistics, whenever a table size exceeds a certain threshold.
SAMPLE cannot be used with the FULLSCAN option. When neither SAMPLE nor FULLSCAN is specified, the query optimizer uses sampled data and computes the sample size by default.
We recommend against specifying 0 PERCENT or 0 ROWS. When 0 PERCENT or ROWS is specified, the statistics object is updated but does not contain statistics data.
For most workloads, a full scan is not required, and default sampling is adequate.
However, certain workloads that are sensitive to widely varying data distributions may require an increased sample size, or even a full scan.
For more information, see the CSS SQL Escalation Services blog.
RESAMPLE
Update each statistic using its most recent sample rate.
Using RESAMPLE can result in a full-table scan. For example, statistics for indexes use a full-table scan for their sample rate. When none of the sample options (SAMPLE, FULLSCAN, RESAMPLE) are specified, the query optimizer samples the data and computes the sample size by default.
PERSIST_SAMPLE_PERCENT = < ON | OFF >
When ON, the statistics will retain the set sampling percentage for subsequent updates that do not explicitly specify a sampling percentage. When OFF, statistics sampling percentage will get reset to default sampling in subsequent updates that do not explicitly specify a sampling percentage. The default is OFF.
[!NOTE] If AUTO_UPDATE_STATISTICS is executed, it uses the persisted sampling percentage if available, or use default sampling percentage if not. RESAMPLE behavior is not affected by this option.
[!TIP] DBCC SHOW_STATISTICS and sys.dm_db_stats_properties expose the persisted sample percent value for the selected statistic.
Applies to: SQL Server 2016 (13.x) (starting with SQL Server 2016 (13.x) SQL Server 2016 (13.x) SP1 CU4) through SQL Server 2016 (13.x) SQL Server 2016 (13.x) SQL Server 2017 (starting with SQL Server 2016 (13.x) SQL Server 2016 (13.x) SQL Server 2017 SQL Server 2017 (14.x) CU1).
ON PARTITIONS ( < <partition_number> | <range> >[, …n] ) ] Forces the leaf-level statistics covering the partitions specified in the ON PARTITIONS clause to be recomputed, and then merged to build the global statistics. WITH RESAMPLE is required because partition statistics built with different sample rates cannot be merged together.
Applies to: SQL Server 2014 (12.x) through SQL Server 2014 (12.x) SQL Server 2017
ALL | COLUMNS | INDEX
Update all existing statistics, statistics created on one or more columns, or statistics created for indexes. If none of the options are specified, the UPDATE STATISTICS statement updates all statistics on the table or indexed view.
NORECOMPUTE
Disable the automatic statistics update option, AUTO_UPDATE_STATISTICS, for the specified statistics. If this option is specified, the query optimizer completes this statistics update and disables future updates.
To re-enable the AUTO_UPDATE_STATISTICS option behavior, run UPDATE STATISTICS again without the NORECOMPUTE option or run sp_autostats.
[!WARNING]
Using this option can produce suboptimal query plans. We recommend using this option sparingly, and then only by a qualified system administrator.
For more information about the AUTO_STATISTICS_UPDATE option, see ALTER DATABASE SET Options (Transact-SQL).
INCREMENTAL = < ON | OFF >
When ON, the statistics are recreated as per partition statistics. When OFF, the statistics tree is dropped and SQL Server re-computes the statistics. The default is OFF.
If per partition statistics are not supported an error is generated. Incremental stats are not supported for following statistics types:
- Statistics created with indexes that are not partition-aligned with the base table.
- Statistics created on Always On readable secondary databases.
- Statistics created on read-only databases.
- Statistics created on filtered indexes.
- Statistics created on views.
- Statistics created on internal tables.
- Statistics created with spatial indexes or XML indexes.
Applies to: SQL Server 2014 (12.x) through SQL Server 2014 (12.x) SQL Server 2017
MAXDOP = max_degree_of_parallelism
Applies to: SQL Server (Starting with SQL Server SQL Server 2016 (13.x) SP2 and SQL Server SQL Server 2016 (13.x) SQL Server 2017 (14.x) CU3).
Overrides the max degree of parallelism configuration option for the duration of the statistic operation. For more information, see Configure the max degree of parallelism Server Configuration Option. Use MAXDOP to limit the number of processors used in a parallel plan execution. The maximum is 64 processors.
max_degree_of_parallelism can be:
1
Suppresses parallel plan generation.
>1
Restricts the maximum number of processors used in a parallel statistic operation to the specified number or fewer based on the current system workload.
0 (default)
Uses the actual number of processors or fewer based on the current system workload.
<update_stats_stream_option> Identified for informational purposes only. Not supported. Future compatibility is not guaranteed.
Remarks
When to Use UPDATE STATISTICS
For more information about when to use UPDATE STATISTICS, see Statistics.
Limitations and Restrictions
- Updating statistics is not supported on external tables. To update statistics on an external table, drop and re-create the statistics.
- The MAXDOP option is not compatible with STATS_STREAM, ROWCOUNT and PAGECOUNT options.
- The MAXDOP option is limited by the Resource Governor workload group MAX_DOP setting, if used.
Updating All Statistics with sp_updatestats
For information about how to update statistics for all user-defined and internal tables in the database, see the stored procedure sp_updatestats (Transact-SQL). For example, the following command calls sp_updatestats to update all statistics for the database.
Determining the Last Statistics Update
To determine when statistics were last updated, use the STATS_DATE function.